

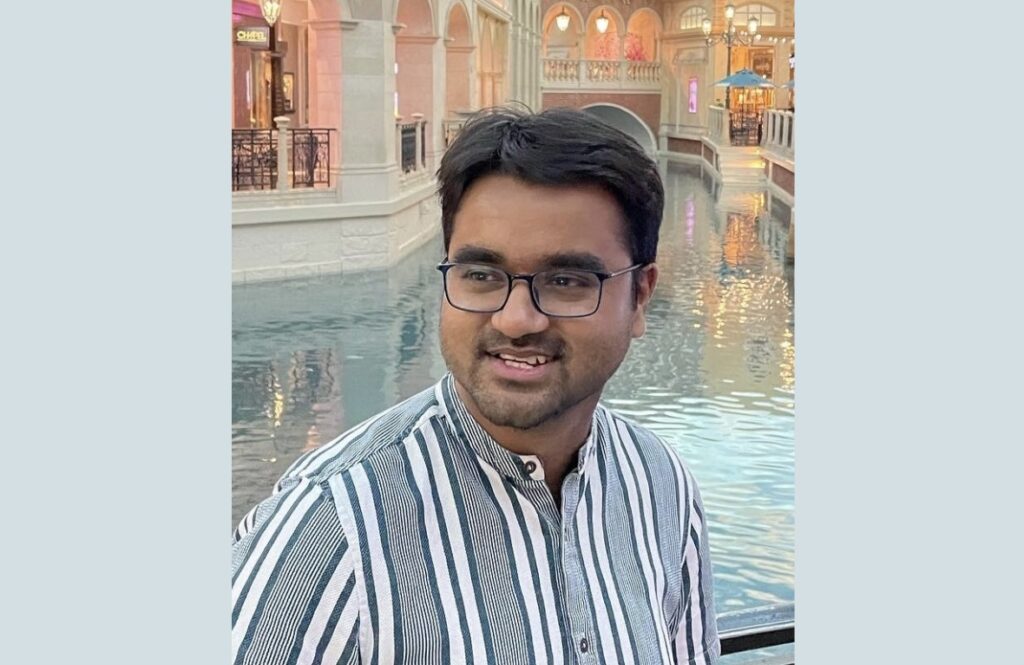
In an interview, Aniket Roy shared insights from his PhD research at Johns Hopkins University, focusing on resource-constrained image generation and visual understanding. His work, supervised by Professor Rama Chellappa, aimed to enhance the efficiency and adaptability of generative models in computer vision tasks, particularly under limited data conditions.
Roy's research included the development of several innovative frameworks, such as FeLMi for few-shot learning and Cap2Aug for caption-guided multimodal augmentation. These methods address challenges like data scarcity and aim to improve the quality of generated images while maintaining high visual fidelity. His work on diffusion models, particularly the introduction of DiffNat, seeks to enhance the perceptual realism of generated images, which is crucial for practical applications.
Looking ahead, the advancements in generative AI that Roy has contributed to could significantly impact various fields requiring efficient and adaptable visual systems. No further timeline was disclosed at the time of publication.
Editor's Note
Aniket Roy's research highlights the growing importance of efficiency in generative AI, particularly in resource-constrained environments. As industries increasingly adopt AI for visual tasks, understanding how to optimize these models will be critical for enhancing performance while managing costs and data limitations. This trend reflects a broader shift towards more sustainable and practical AI solutions in the technology landscape.















Leave a comment