On Tuesday, the Qwen team unveiled a new robotics suite that includes three foundational models: Qwen-RobotNav, Qwen-RobotManip, and Qwen-RobotWorld. These models are designed to integrate language processing with various physical actions, enhancing the capabilities of mobile robotics. Qwen-RobotNav, in particular, advances vision-language integration by employing controllable observation encoding and tool-based interfaces. This innovative model consolidates four essential tasks into a single framework, which includes instruction following and goal-directed navigation. The release aims to improve the interaction between language and robotics, paving the way for more sophisticated and versatile robotic applications.


Robot Manufacturer
Software & Algorithm Provider
Mobile Robot (AGV/AMR)
Human-Machine Interaction
Perception & Vision
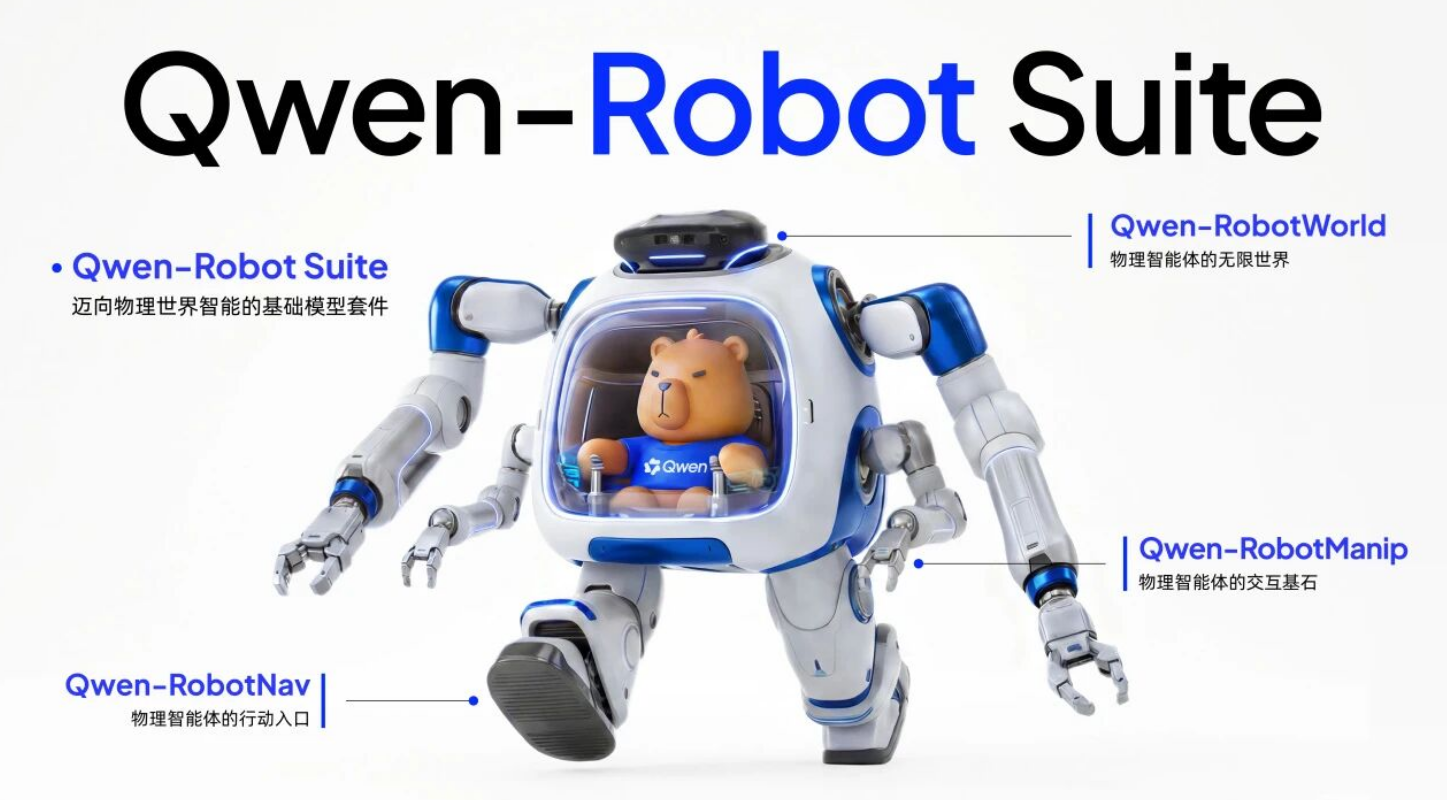
Original from TechNode.com: Alibaba unveils Qwen-Robot series with three foundation models for embodied AI
Alibaba unveils Qwen-Robot series with three foundation models for embodied AI
RobotToday Initiative
Robotics needs a service framework.
RSF defines a common language for robot service capability, lifecycle operations, certification pathways, and service-provider networks.
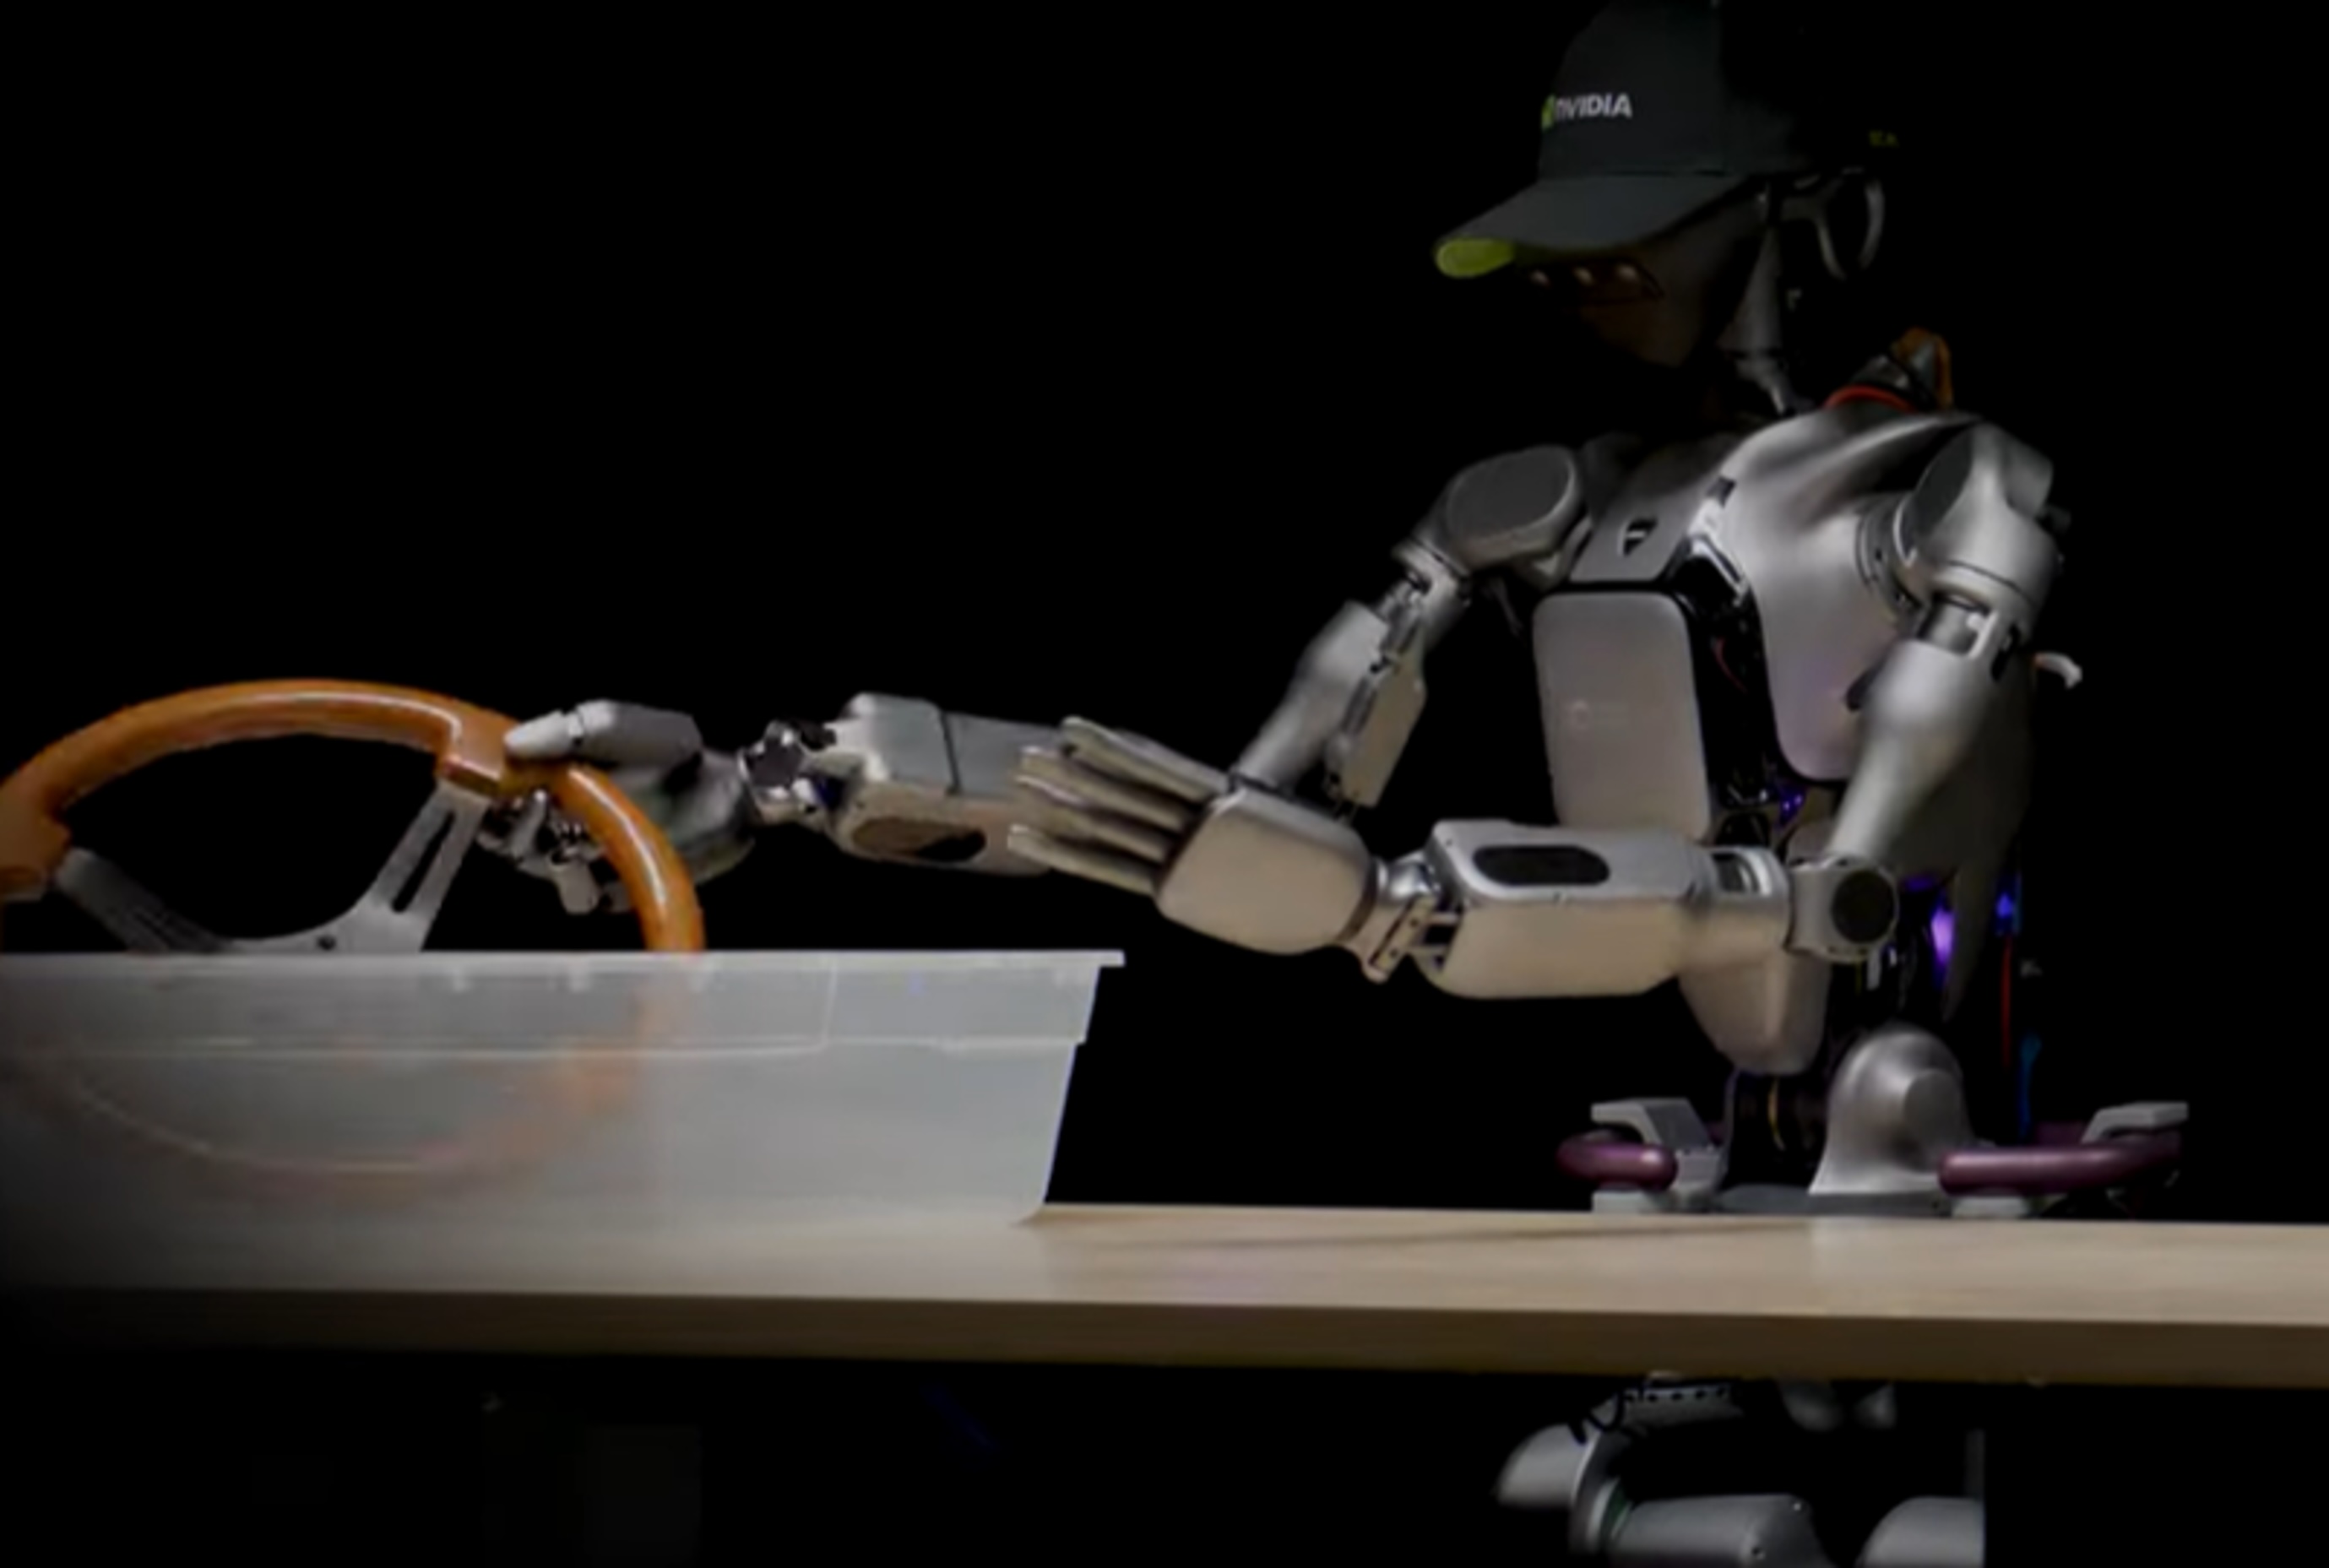
Understanding the Necessity of End-of-Line Testing Equipment for Manufacturers
End-of-line testing is crucial for manufacturers to verify product quality before it leaves the production line. This testing serves as a final quality checkpoint, ensuring that products meet performance standards. Common tests include assessing balance, vibration, torque, pressure, electrical performance, dimensions, and functional operation. The signifi...
Engineering Manufacturing balance testing
Leap Motor Introduces Fully Self-Developed Embodied Intelligent Robot at Technology Day
On September 16, Leap Motor announced the completion of its fully self-developed embodied intelligent robot during its 2026 Technology Day. The company has independently mastered all core components, including motors, controllers, batteries, perception algorithms, and computing platforms. This comprehensive self-research system allows Leap Motor to transf...
Robotics Automotive Technology AI
Humanoid Robot Manufacturers Face Profit Challenges Amid Shift to Dexterous Hands
Humanoid robot manufacturers are struggling with profitability as they face high costs and low margins. A humanoid robot priced at 85,000 yuan typically yields a gross margin of around 10%, with some companies like Yushu Technology projecting a rise to 60.13% by 2025, despite risks from price wars. The cost of dexterous hands, which accounts for 10% to 15...
Humanoid Robots Dexterous Hands Robotics Manufacturing
Innovation Works Venture Expo 2026: 58 Pittsburgh Startups Pitch to Investors
58 health, deep tech and robotics startups pitched at Innovation Works Venture Expo 2026 in Pittsburgh. Full company list, program and 2025 funding data.
Market and Business News
Blueworm Embodied Unveils Mantis Standard Modular Wheeled Humanoid Priced from RMB 9,800
Blueworm Embodied has launched the Mantis Standard, a modular wheeled humanoid robot priced starting at RMB 9,800. This innovative robot features 22 degrees of freedom and a single-arm payload capacity of 7 kg, enhancing its versatility in various applications. The introduction of the Mantis Standard is significant as it combines advanced capabilities wit...

The Missing Price: What Non-Disclosure Reveals About the Humanoid Market
Of 131 announced robot models, 33 publish no price. US makers withhold at twice the rate of Chinese ones — and the reason is stage, not strategy.
Market and Business News
Tesla's New Software Update Enables Collision Avoidance Without Full Self-Driving Activation
Tesla has announced the rollout of its v14.3.9 software update, which allows vehicles to steer away from imminent collisions even if the driver has not activated Full Self-Driving (FSD). This feature aims to enhance safety and is part of a broader strategy to increase FSD subscriptions, which have seen a 56% year-over-year growth, reaching 1.48 million. T...
Skild AI Introduces S1 Robot Foundation Model for Learning from Video Demonstrations
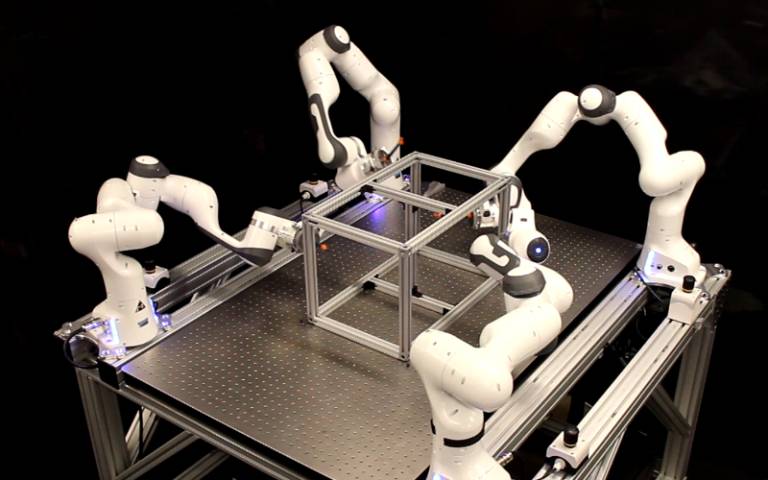
Skild AI has launched the S1, a groundbreaking robotics foundation model that allows robots to learn manipulation tasks from just one video demonstration. This innovative model eliminates the need for task-specific fine-tuning or post-training, streamlining the learning process for robotic systems. The significance of the S1 model lies in its use of in-co...
Computing Design News
IMTS 2026 Preview: Record Orders and the Automation Story
IMTS 2026 opens in Chicago with 1,788 exhibitors and record H1 machine tool orders. What the USMTO data says about automation, and the booths to see.
Market and Business News
ROBOTTODAY WEEKLY September 7 – 11, 2026
This week in robotics: JD.com plans to deploy three million robots across its logistics network, XPeng commissions its IRON humanoid production line, FANUC and Google launch an AI arc-welding agent, and Unitree shares fall 53% from their post-IPO high. September 7–11, 2026.
RobotToday Weekly
China’s Dexterous Hand Industry, 2026 Part 3 — The Players
Five vendor archetypes, MIR’s composite top ten, eight company profiles and six field deployments — every firm linked to the RobotToday supplier directory.
Components and Hardware Humanoids
Manufacturers Embrace Agentic AI Amidst Lack of Governance Plans
Recent research highlights a significant gap in governance as manufacturers increasingly adopt agentic AI technologies. The focus has primarily been on the delay in establishing governance frameworks, yet there is less emphasis on the practical steps needed to address this gap. As AI systems evolve from merely summarizing reports to making autonomous deci...
SAISON ROBOT/LingYu Robotics 灵御智能
China
LingYu Robotics to Showcase Teleoperation and Embodied AI Solutions at Automate 2026 Subscribe for the Latest Automate Show Updates Copyright © 2013-2026 A3 Automate.
Yuanqi Innovation (Xiamen) Robot Co., Ltd. 元启创新(厦门)机器人有限公司
China
yuanqirobot.com resolves to a Xiamen-based robot company; directory lists it as Qingdao YuanQi Intelligent Robot Tech — city mismatch requires verification.
OM Robot Technology Co. Ltd. 东莞全向机械科技有限公司
China
Chinese manufacturer of mecanum wheels, omnidirectional wheel bases, and mobile robotic platforms for AGV applications.
IT+Robotics (IT)
Italy
IT+Robotics develops 3D machine vision systems for industrial robotics including EyeT+ random bin-picking, adaptive machining path generation and automated 3D completeness inspection for production quality control.
Magellium (FR)
France
French software and data analytics company specializing in satellite image processing, remote sensing, and geospatial intelligence. Serves space, defense, and environmental monitoring sectors. Website unavailable at scrape time.
Ortelio Ltd
United Kingdom
Ortelio Ltd is a UK cloud robotics research company founded in 2011 that develops AI platforms giving robots intelligence for service and healthcare tasks.
The Mobile Robot Company
Denmark
Danish startup founded by ex-MiR and Geekplus veterans, won a 2026 IFOY AWARD for its J1600 self-driving pallet jack.
AMR Integration
United States
U.S. autonomous mobile robot integrator delivering turn-key AMR deployments using MiR, AGILOX and Universal Robots platforms.

Robot Center
United Kingdom
UK-based collaborative and service robotics provider supplying AMRs, cobots, and inspection robots to public and private sector organizations.
Human in Motion Robotics
Canada
Canadian company developing hands-free lower-limb exoskeletons for spinal cord injury and stroke rehabilitation.
LG Display
Korea, Republic of (South)
Seoul display maker (KRX:034220, NYSE:LPL), formed 1999, that launched plastic OLED humanoid-robot face panels for industrial settings in 2026.
Roboblock System Co., Ltd.
Korea, Republic of (South)
South Korean robotics distribution and development company founded in 1997; supplies AI robots, drones, humanoid kits, and VR/AR systems internationally.
Join the RobotToday community on LinkedIn
Daily robotics news, in-depth analysis, conference highlights, and discussions with professionals worldwide.




Leave a comment