


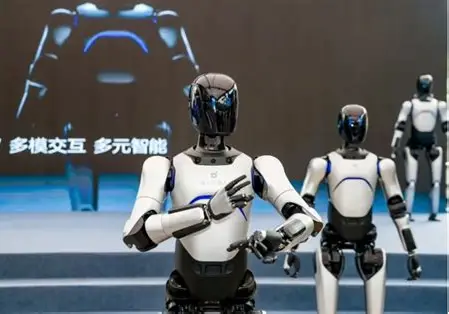
Recently, DailyOmni announced its latest evaluation results, revealing that WITA-Omni Preview, developed by Zhiyuan, topped the rankings with a score of 85.21. This model surpassed leading competitors such as Qianwen, Gemini, Doubao, and NVIDIA, achieving first place in six out of eight sub-indicators. DailyOmni is recognized as an authoritative third-party ranking for assessing audio-video temporal alignment and cross-modal reasoning capabilities.
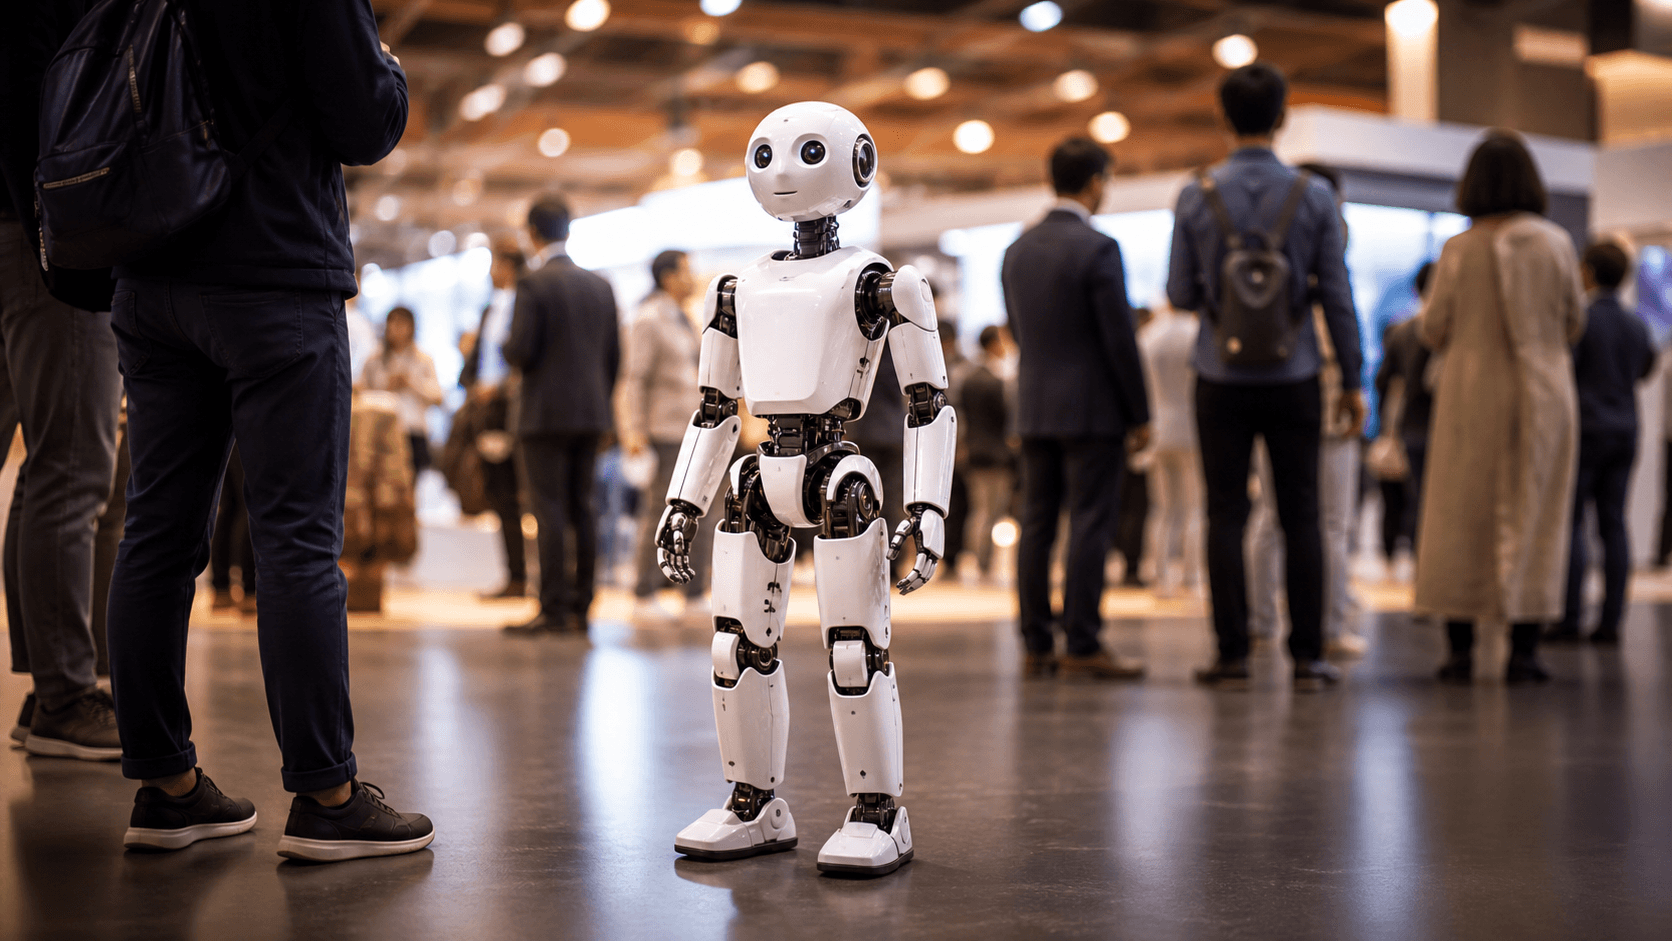
The significance of this achievement lies in WITA-Omni's advanced ability to integrate audio and visual information, which is crucial for humanoid robots interacting in dynamic physical environments. Unlike traditional multimodal models that primarily focus on digital content, WITA-Omni excels in real-time judgment of sound attribution and event sequencing, addressing a key bottleneck in human-robot interaction.
Looking ahead, Zhiyuan aims to enhance the WITA-Omni model further, focusing on its application in various commercial and public service scenarios. No further timeline was disclosed at the time of publication.
Editor's Note
The success of WITA-Omni Preview highlights the growing importance of advanced multimodal understanding in robotics. As humanoid robots become more integrated into everyday environments, their ability to process and respond to complex sensory inputs will be crucial for effective human-robot interaction. This development could significantly impact sectors such as customer service, healthcare, and entertainment.













Leave a comment