Industry Briefing
A single destination for timely, editor-curated robotics news from around the world.

Mimic Robotics Unveils FLUX-mimic Video-Action Models at Audi's Factory
Mimic Robotics has launched FLUX-mimic, an advanced Video-Action Model developed with Black Forest Labs, designed for industrial automation. This model allows robots to learn complex manipulation tasks in real-world settings, significantly reducing the time required for training and deployment. The introduction of FLUX-mimic is crucial as it addresses the limitations of traditional robot learning methods, which often rely on extensive demonstration data. By utilizing a generative video model, FLUX-mimic can fine-tune tasks with as little as 30 minutes of data, compared to the 30 hours typically needed, thereby streamlining the deployment process. Looking ahead, Mimic Robotics is collaborating with Audi to implement FLUX-mimic in their highly automated production network. This partnership aims to enhance the efficiency of industrial automation, paving the way for smart factories where AI and robots work alongside human employees to optimize production processes.
Artificial Intelligence Computing Design News audi Black Forest Labs
Skild AI Introduces S1 Robot Foundation Model for Learning from Video Demonstrations
Skild AI has launched the S1, a groundbreaking robotics foundation model that allows robots to learn manipulation tasks from just one video demonstration. This innovative model eliminates the need for task-specific fine-tuning or post-training, streamlining the learning process for robotic systems. The significance of the S1 model lies in its use of in-context learning, which parallels the prompting techniques utilized in large language models. This capability enables operators to simply demonstrate a task via video, making it easier for robots to acquire new skills efficiently and effectively. Looking ahead, the implications of the S1 model could reshape how robots are trained and deployed across various industries. As Skild AI continues to develop this technology, industry professionals should monitor advancements and potential applications of the S1 model in real-world scenarios. No further timeline was disclosed at the time of publication.
Computing Design News Software artificial intelligence Autonomous robots
AgiBot Launches GE-Act 2.0 Native World-Action Model with Enhanced Data Scaling
AgiBot has introduced GE-Act 2.0, a native world-action model that has been pretrained from random initialization using embodied data. This new model has significantly scaled from 300 to 30,000 hours of training, enabling it to perform zero-shot skills, including towel folding, across two different robot embodiments. The release of GE-Act 2.0 is significant as it demonstrates AgiBot's commitment to advancing robotic capabilities through extensive data scaling. By increasing the training hours, the model can now execute complex tasks without prior specific training, showcasing the potential for greater versatility in robotic applications. Looking ahead, it will be important to monitor how GE-Act 2.0 performs in real-world scenarios and whether it can be adapted for additional tasks beyond towel folding. No further timeline was disclosed at the time of publication.
Comprehensive Survey on Vision-Language-Action Models for Embodied AI
A comprehensive survey on vision-language-action models for embodied artificial intelligence has been published in the Journal of Field Robotics. This survey explores the integration of visual perception, language understanding, and action execution in AI systems, highlighting the advancements and challenges in this interdisciplinary field. The significance of this survey lies in its potential to enhance the development of more capable and intelligent robotic systems. By examining the interplay between vision, language, and action, researchers can better understand how to create AI that can interact with the world in a more human-like manner, which is crucial for applications in various sectors. Looking ahead, the survey may pave the way for future research initiatives aimed at improving embodied AI systems. No further timeline was disclosed at the time of publication.
SURVEY ARTICLE
Alibaba Cloud Introduces Wan3.0 Video Generation Model with 30-Second Clips
Alibaba Cloud has launched Wan3.0, a new video-generation model capable of producing clips up to 30 seconds long. This model accepts various document formats, including DOC, XLS, PPT, PDF, and Markdown, as input. Wan3.0 had been in public beta since early August, allowing users to test its capabilities. The introduction of Wan3.0 is significant as it enhances the video generation process by improving instruction following, shot consistency, and audio quality. This advancement positions Alibaba Cloud as a competitive player in the video generation market, catering to businesses looking for efficient content creation solutions. From August 24 to September 23, selected platforms will provide a temporary 30% discount on Wan3.0 API pricing. This promotional offer may attract more users to explore the model's features and capabilities, potentially leading to increased adoption in various sectors. No further timeline was disclosed at the time of publication.
News Feed
Beta Infinite Unveils BetaWAM 0.1 World Action Model for Complex Tasks
Beta Infinite has introduced its BetaWAM 0.1 world action model, showcasing a robot capable of autonomously completing complex, long-range tasks in dynamic environments. This model addresses the limitations of existing technologies that primarily focus on single-point actions or fixed operations. The significance of BetaWAM 0.1 lies in its ability to perform multiple objectives without human intervention, overcoming challenges such as obstructions and sudden changes in the environment. This advancement is crucial for the future of consumer robotics, as it aims to bridge the gap between action intelligence and task intelligence. Looking ahead, Beta Infinite's approach to integrating memory and spatial understanding into its robotic systems could redefine operational capabilities in the robotics sector. No further timeline was disclosed at the time of publication.
Embodied Intelligence Robotics Task Automation AI Consumer Robotics
LTX Unveils LTX-2.5 Open World Model for Enhanced Video and Physical AI Applications
LTX has introduced LTX-2.5, an advanced version of its open-weights world model, enhancing capabilities for video generation and physical AI. This model boasts improvements in visual quality, prompt understanding, and generation speed, allowing developers to customize it on their hardware. With over 33 million downloads, LTX-2.5 is positioned as a foundational model for applications in film production, robotics, and real-time rendering. The significance of LTX-2.5 lies in its ability to model environmental changes over time, a critical feature for robotics and physical AI. According to Zeev Farbman, co-founder and CEO of LTX, the model addresses challenges unique to world models, such as maintaining consistency in motion and sound. By offering an open model, LTX empowers teams to retain control over their hardware and intellectual property while delivering industry-leading quality. Looking ahead, LTX has rebuilt much of the generation pipeline for LTX-2.5, introducing features like native multishot generation and a new diffusion video decoder. These enhancements aim to improve visual output and prompt understanding, making LTX-2.5 a versatile tool for developers. No further timeline was disclosed at the time of publication.
Computing Design Software artificial intelligence asteria comfyui
Stardust AI Launches Lumo-2: Innovative Robot Action Model for Home Automation
On July 15, Stardust AI introduced its second-generation embodied base model, Lumo-2, which is the industry's first household latent world-action model. This launch includes the physical AI symbiotic agent, Agent Philia, enhancing their full-stack architecture of AI models, embodied operating systems, and rope-driven entities. The company will showcase its 'trinity' multi-scenario implementation solutions at the World Artificial Intelligence Conference in Shanghai from July 17 to 20. Lumo-2 autonomously performs 22 complex household tasks, demonstrating industry-leading capabilities in task range and complexity. This model addresses the challenges faced by robots in open environments, such as the inability to explain actions and the high costs of training complex skills. By predicting future scenarios before generating actions, Lumo-2 aims to overcome these bottlenecks and improve the practical execution of robotic tasks. Looking ahead, Stardust AI plans to enhance the scalability of Lumo-2 by expanding training data diversity and exploring efficient data engineering paradigms. The team is also focused on advancing real-world interactive learning to enable robots to adapt and evolve autonomously in dynamic environments. No further timeline was disclosed at the time of publication.
Household Robotics Physical AI AI Models Robotic Automation
Humanoid Robots Enhanced by AI Controller for Translating Commands into Actions
Humanoid robots, designed to mimic human limbs and body structures, are being enhanced by an AI controller that translates virtual reality, video, and language commands into actionable movements. This advancement aims to simplify the teaching process for these robots, which often struggle with executing humanlike movements reliably. The significance of this development lies in its potential to streamline the deployment of humanoid robots across various environments, including homes and workplaces. By improving the efficiency of command translation, the AI controller could reduce the time and effort required to train these robots, making them more accessible for practical applications. Looking ahead, the focus will be on the effectiveness of the AI controller in real-world scenarios and its ability to adapt to diverse tasks. No further timeline was disclosed at the time of publication.
Robotics
DeepSeek Expands Engineering Team by 150 as ByteDance Accelerates Video Generation
DeepSeek has announced a significant expansion of its engineering team, adding 150 new engineers to enhance its capabilities in AI and robotics. This move reflects the growing demand for advanced AI solutions in various sectors, particularly in the development of large models that go beyond traditional parameter counts. The expansion is crucial as it positions DeepSeek to better compete in the rapidly evolving AI landscape, where companies are increasingly focusing on innovative applications of technology. By bolstering its workforce, DeepSeek aims to accelerate the development of its products and services, particularly in the realm of video generation, where ByteDance is also making strides. Looking ahead, industry observers will be keen to see how this recruitment drive impacts DeepSeek's product offerings and market position. No further timeline was disclosed at the time of publication.
Robotics Automation AI
ByteDance Prepares AI Model for Real-Time Spatial Video Generation Competing with Meta and Alphabet
ByteDance Ltd. is developing an AI model focused on real-time spatial video generation, positioning itself against major players like Meta Platforms Inc. and Alphabet Inc. This initiative highlights the growing competition in the AI sector, particularly in applications relevant to robotics and autonomous systems. The significance of ByteDance's efforts lies in its potential to enhance capabilities in robotics and autonomous systems, areas that are increasingly reliant on advanced AI technologies. By entering this competitive landscape, ByteDance aims to carve out a niche in a market that is rapidly evolving and attracting significant attention from industry leaders. Looking ahead, stakeholders should monitor ByteDance's progress in this AI model development, as it could influence trends in spatial video applications and their integration into robotics. No further timeline was disclosed at the time of publication.

Google Launches Sign-Language Translation Model for Enhanced User Interaction
Google has introduced a sign-language translation model capable of converting intricate body movements into text, utilizing over 100,000 hours of data from more than 50 sign languages. This technology, known as sign-language-to-text (SL2T), is being integrated into consumer devices, starting with American Sign Language (ASL) on Pixel 11. Users can now sign to search the web, compose messages, and engage with Google’s Gemini, enhancing accessibility for the Deaf community. The significance of this development lies in its ability to address the unique complexities of sign languages, which possess their own grammar and vocabulary. Unlike traditional speech transcription, sign-language translation involves interpreting simultaneous hand movements, facial expressions, and body posture. Google’s SL2T model employs computer vision techniques to convert the signer’s movements into a structured format before translating them into text, ensuring a more accurate representation of the signed language. Looking ahead, Google aims to refine the SL2T system further by addressing practical challenges such as latency and performance for various signing styles. The involvement of Deaf users and organizations throughout the development process underscores the commitment to creating a user-friendly and effective translation tool. No further timeline was disclosed at the time of publication.
AI and Robotics
Omega-0 Model Achieves 81.8 Percent Success in Home Tasks by Nanyang Technological University and Partners
Researchers from Nanyang Technological University, Peking University, HKUST (GZ), and Beijing Academy of Artificial Intelligence (BAAI) have introduced Omega-0, a latent-prediction world action model. This innovative model enables a humanoid robot to perform multiple actions simultaneously, including walking, looking, and working. The significance of Omega-0 lies in its impressive performance, achieving an 81.8 percent success rate across 11 real home tasks. This success surpasses that of previous models such as pi-0.5, EgoVLA, GR00T-N1.7, and psi-0, highlighting advancements in robotic capabilities for practical applications in domestic environments. Looking ahead, the development of Omega-0 suggests a growing trend in robotics focused on enhancing the functionality of humanoid robots in everyday tasks. No further timeline was disclosed at the time of publication.

Dyna Robotics Launches DYNA-2 Model Trained on 1 Million Hours of Human Video
Dyna Robotics has introduced its DYNA-2 World-Action Model, trained on over 1 million hours of human video. This innovative approach aims to address the challenges of teaching robots to perform physical tasks by leveraging human egocentric video instead of traditional robot action data. The significance of this development lies in its potential to enhance task success rates in high-precision manufacturing, with Dyna reporting an increase from 20% to 80%-90% due to the extensive pre-training. The model's architecture allows for knowledge transfer across various robotic platforms, demonstrating adaptability with minimal fine-tuning. Looking ahead, Dyna Robotics envisions DYNA-2 as a pivotal advancement in robotics, enabling robots to learn new tasks without extensive robot-specific training data. No further timeline was disclosed at the time of publication.
AI and Robotics
Muka Robotics' LJM Model Secures Global Second Place at WorldArena Using 32 GPUs
Muka Robotics has achieved a remarkable feat with its LJM Latent Joint-conditional Model, securing the second position globally at WorldArena with a motion quality score of 89.17 using only 32 Zhenwu 810E GPUs. This accomplishment highlights the model's innovative dual-expert architecture, which emphasizes physical understanding rather than solely focusing on video generation quality. This achievement is significant as it showcases Muka Robotics' commitment to advancing the field of robotics by prioritizing physical logic in its models. The successful integration of a limited number of GPUs to achieve high motion quality demonstrates the potential for efficiency in computational resources while maintaining performance standards in robotics applications. Looking ahead, it will be important to monitor how Muka Robotics continues to develop its technologies and whether this dual-expert architecture will influence future models in the industry. No further timeline was disclosed at the time of publication.
Technology
Tencent Open-Sources Three Embodied Foundation Models for Enhanced Robot Performance
Tencent has announced the open-source release of three embodied foundation models during the WAIC 2026 event. These models include a Visual Language Model (VLM) designed for scene understanding, the RxBrain cognitive model that facilitates planning with visual states, and the VLA model, which supports continuous action at frequencies between 500 to 1000Hz. This development is significant as it aims to enhance robot reaction speed and cognitive capabilities, addressing critical challenges in robotic performance. The introduction of these models is expected to advance the field of robotics by providing developers with powerful tools to improve the efficiency and effectiveness of robotic systems. Looking ahead, the industry will be keen to observe how these open-source models are adopted and integrated into various robotic applications. No further timeline was disclosed at the time of publication.
Technology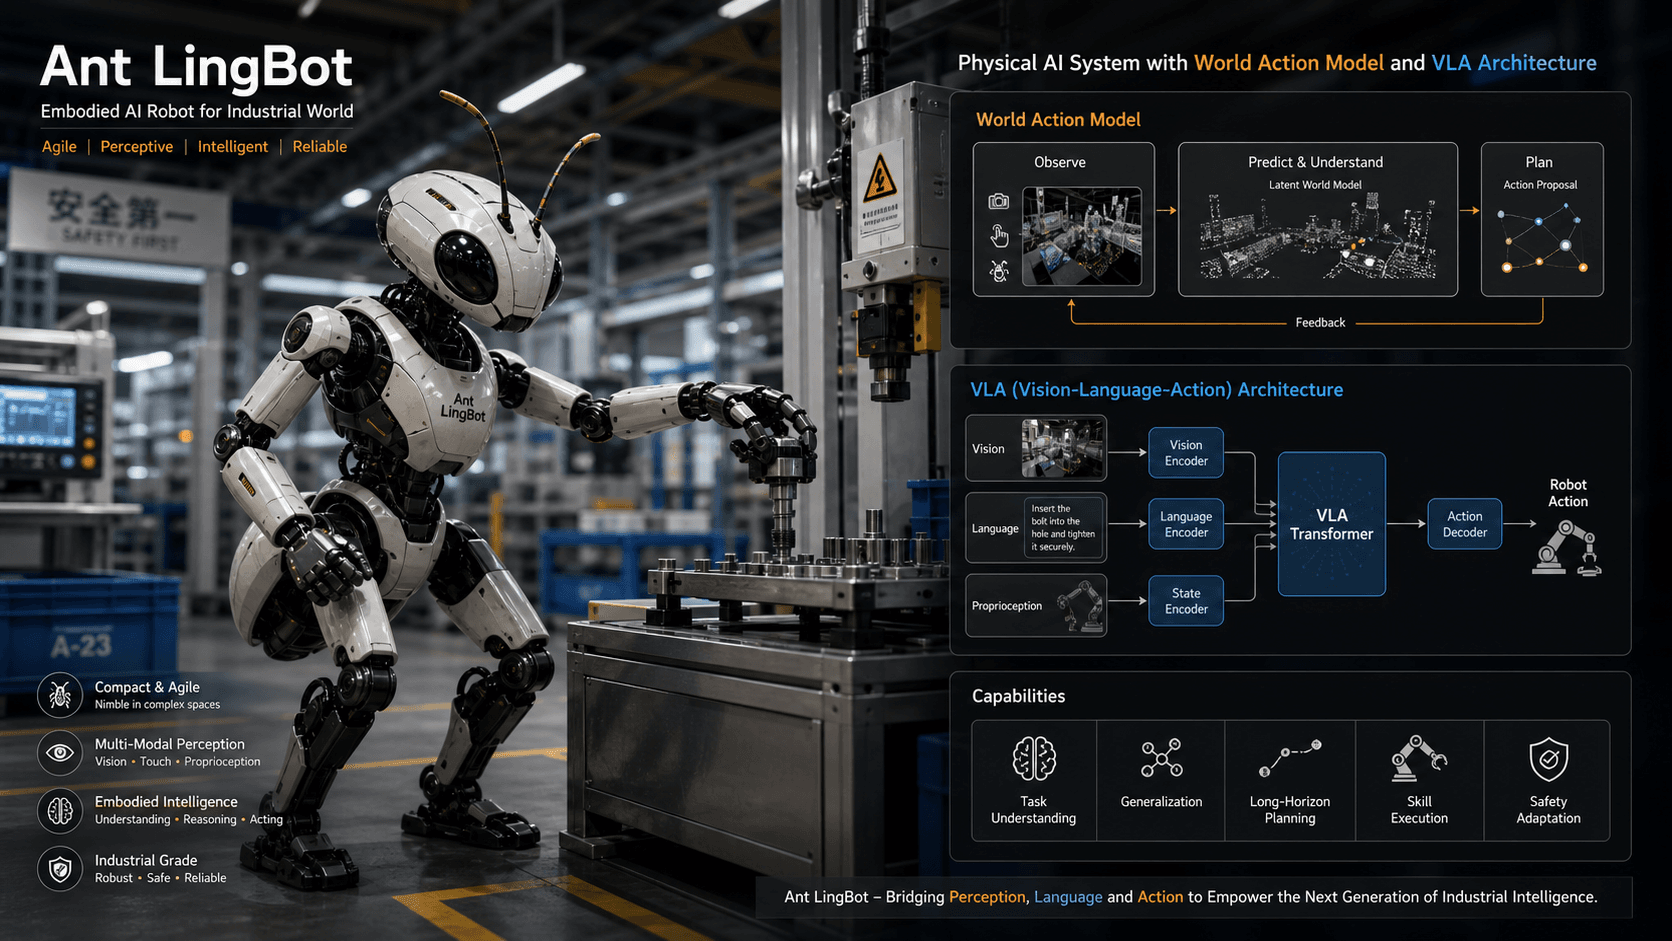
Ant LingBot Unveils Six Open-Source AI Models Amid Data Challenges
Ant LingBot, a subsidiary of Ant Group, has launched six open-source embodied AI models as part of its dual-track strategy focusing on Visual Language Agents (VLA) and world models. This initiative aims to enhance AI capabilities while addressing the growing demand for advanced AI solutions. The significance of this release lies in Ant LingBot's commitment to fostering an open-source ecosystem, which is crucial for collaboration and innovation in the AI field. However, the company is contending with challenges related to data scarcity and competition within the ecosystem, which could impact its development and deployment efforts. Looking ahead, it will be important to monitor how Ant LingBot navigates these challenges and whether it can successfully leverage its dual-track strategy to establish a strong presence in the AI landscape. No further timeline was disclosed at the time of publication.
Technology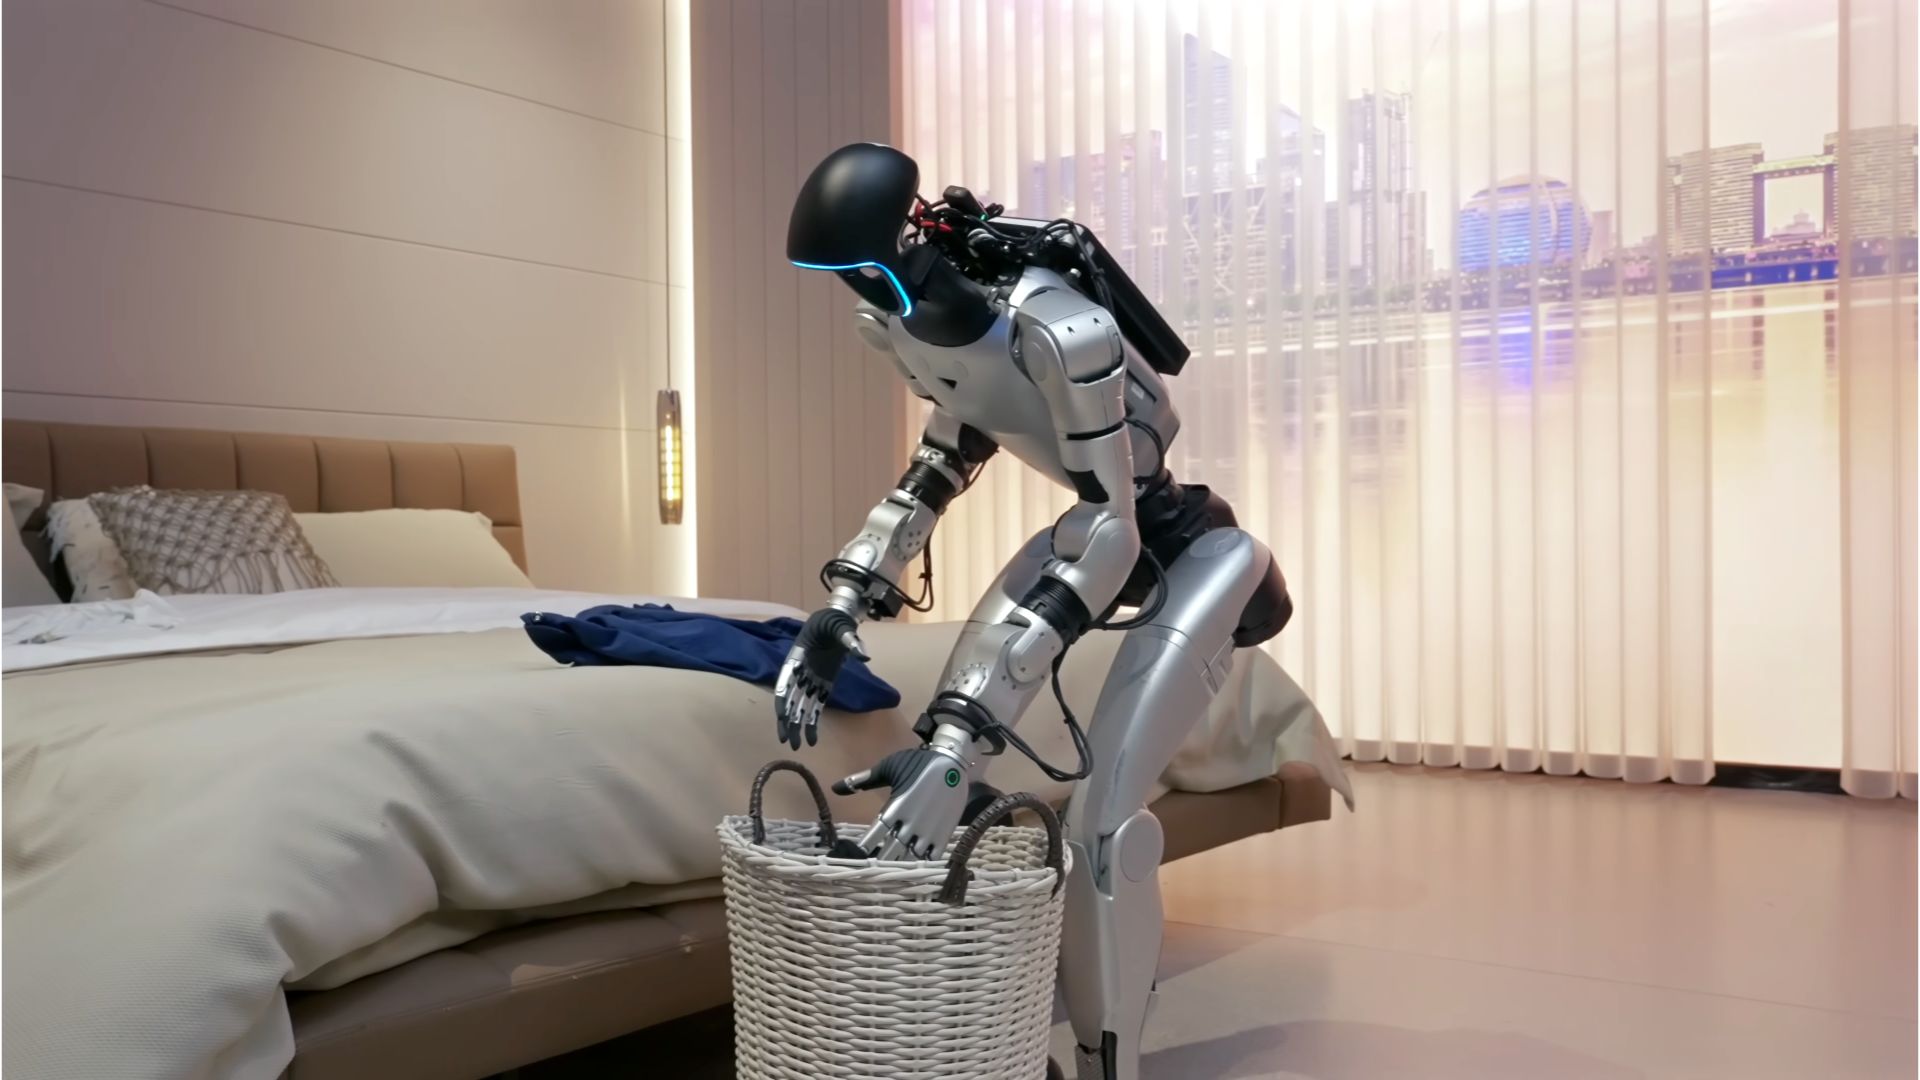
Unitree Launches UnifoLM-OminiA-0.3 for Enhanced Humanoid Robot Interaction and Assistance
Chinese robotics firm Unitree has introduced UnifoLM-OminiA-0.3, a unified AI model designed for humanoid robots. This model facilitates real-time omni-modal interaction, reasoning, dialogue, and whole-body mobile manipulation, targeting home-care and wellness applications. The robots can autonomously perform tasks such as tidying rooms and assisting patients while responding to various inputs. The significance of UnifoLM-OminiA-0.3 lies in its ability to integrate multiple capabilities into a single system, allowing robots to process information from speech, vision, and environmental cues simultaneously. This unified architecture enables seamless task execution, as demonstrated by a humanoid robot that can adjust a hospital bed and respond to user commands mid-task, showcasing continuous human-robot interaction. Looking ahead, the trend towards embodied AI is expected to grow, with developers focusing on integrating vision-language models with robot control. This approach enhances flexibility in dynamic environments like homes and healthcare facilities, where tasks and interactions can vary significantly. No further timeline was disclosed at the time of publication.
AI and Robotics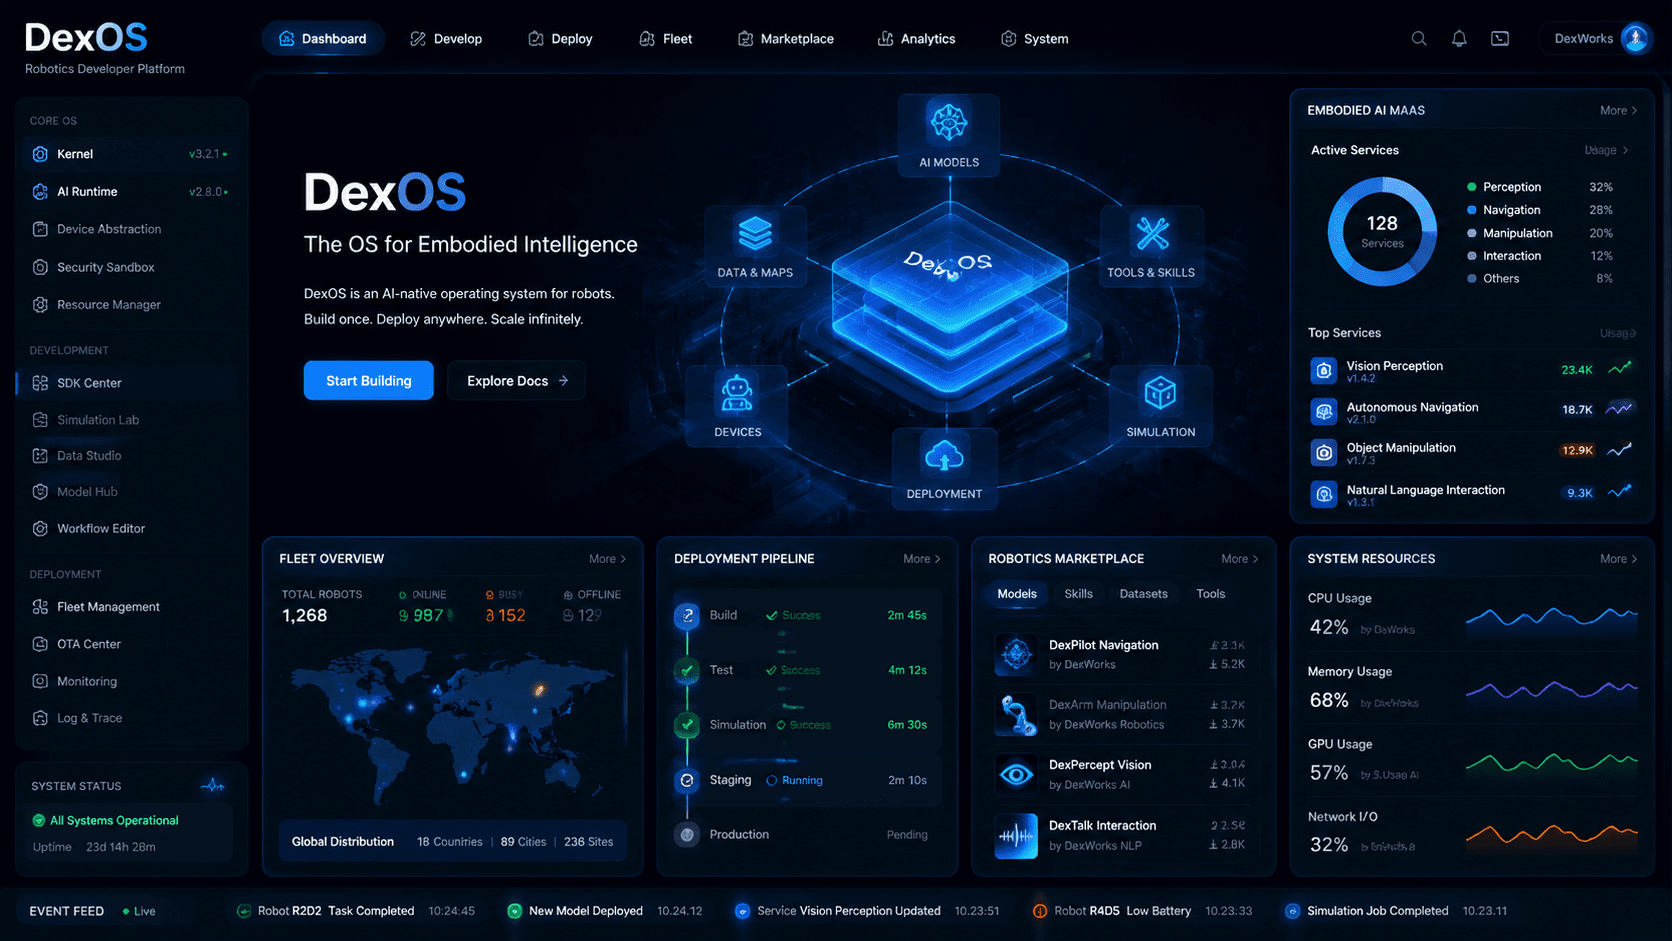
Dexmal Introduces DM0.5 Model and DexOS at Action Developer Conference
Dexmal has launched its DM0.5 foundation model, DexOS operating system, and an embodied Mobility-as-a-Service (MaaS) platform during the Action developer conference. This event took place recently and aims to position Dexmal as a key player in the robotics industry by creating a versatile platform akin to Android for robotics applications. The introduction of the DM0.5 model and DexOS is significant as it seeks to address the challenges of scaling robotic models into practical, real-world scenarios. By providing a unified operating system and a robust foundation model, Dexmal aims to enhance interoperability and functionality across various robotic applications, potentially transforming how developers approach robotics solutions. Looking ahead, Dexmal's next steps involve further development of its MaaS platform and expanding the capabilities of the DM0.5 model. No further timeline was disclosed at the time of publication, but industry watchers will be keen to see how these innovations influence the robotics landscape and attract developer interest.
Robotics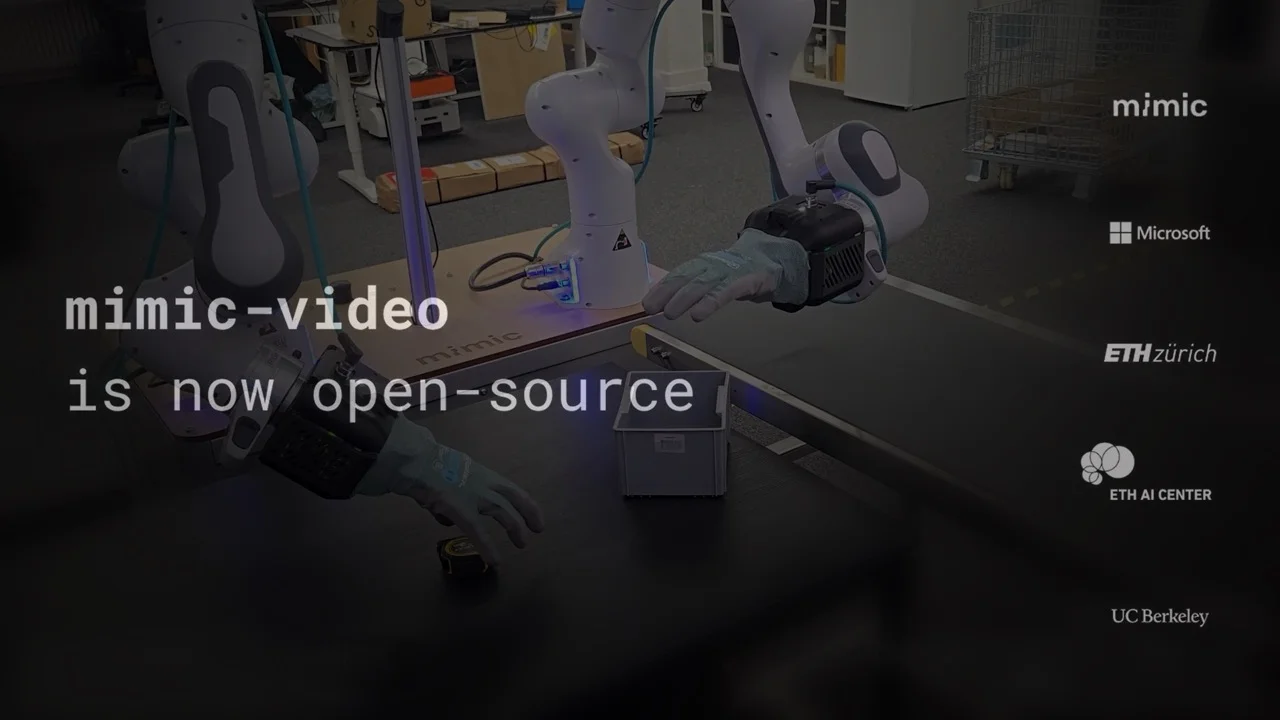
Mimic Robotics Open-Sources "mimic-video" Recipe to Accelerate Video-Action Models
Mimic Robotics, a company based in Zurich, has unveiled its innovative "pixel-to-action" architecture, which is designed to transform the current landscape of artificial intelligence by moving away from traditional static vision-language models. This release, which includes both the code and accompanying research, marks a significant shift towards utilizing dynamic video-based foundations. The initiative aims to enhance the capabilities of AI systems, enabling them to better interpret and respond to visual information in real-time. By sharing this technology, Mimic Robotics seeks to foster advancements in the field and encourage further exploration of video-based AI applications.
Mimic Robotics Europe open-source ETH Zurich
Rhoda AI Hits $1.7B Valuation, Unveils "Direct Video-Action" Model to Bridge the Real-World Gap
Rhoda AI, a technology company based in Palo Alto, has emerged from stealth mode with the announcement of a $450 million Series B funding round. This significant investment will support the development of its innovative "Direct Video-Action" framework, which leverages hundreds of millions of internet videos to educate robots on the principles of physics. The funding aims to enhance the company's capabilities in artificial intelligence and robotics, positioning Rhoda AI at the forefront of technological advancements in these fields. The announcement marks a pivotal moment for the company as it seeks to revolutionize how machines learn and interact with the physical world.
DVA US rhoda-ai
Skild AI Introduces S1 Robot Model Utilizing NVIDIA Physical AI for Task Learning
Skild AI has launched its S1 robot foundation model, designed to learn new tasks from a single video demonstration. This innovative approach utilizes in-context learning, allowing the robot to understand and execute tasks without the need for extensive reprogramming. The model was developed using NVIDIA AI infrastructure, highlighting a collaboration aimed at enhancing adaptable robot intelligence in dynamic environments. The significance of the S1 model lies in its ability to perform unfamiliar tasks, such as plant potting and pancake making, by interpreting video prompts. This method drastically reduces the time and resources typically required for retraining robots, achieving a success rate of 66% in executing new multistep tasks. Skild AI's approach marks a pivotal shift in robotics, moving away from fixed programming to a more flexible, experience-based learning model. Looking ahead, Skild AI is actively deploying the S1 model in various applications, including manufacturing and logistics, with over 60 partnerships established. The collaboration with NVIDIA and Foxconn aims to enhance precision in assembly tasks, showcasing the potential for robots to adapt in real-time to changing conditions on the factory floor. No further timeline was disclosed at the time of publication.
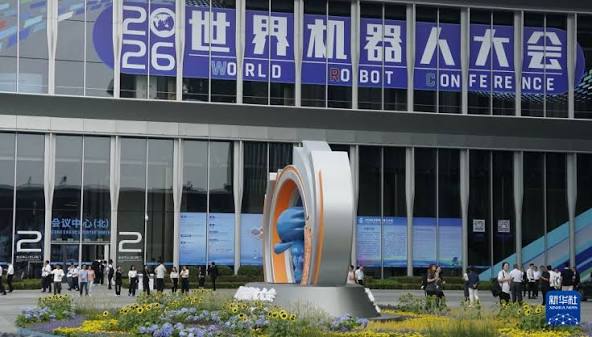
Insights from the 2026 World Robot Conference: Specialized Robots Gain Traction Over General-Purpose Models
At the 2026 World Robot Conference, a clear trend emerged indicating that the embodied intelligence industry is shifting focus from creating general-purpose robots to developing specialized solutions that deliver real value in specific scenarios. Innovations in areas such as garment sewing, biomedical applications, and airport luggage handling highlight this transition. The significance of this shift lies in the ability of specialized robots to address industry-specific challenges, such as labor shortages and rising costs in garment production. For instance, Aitu's humanoid robot is designed solely for garment sewing, showcasing its capability to autonomously identify fabrics and perform precise stitching without the need for constant reprogramming. Looking ahead, the conference revealed advancements in collaborative robotics, with companies exploring multi-robot systems for enhanced efficiency. Notably, Xingyuan Intelligence demonstrated a novel multi-robot collaboration in a jumping rope task, indicating a trend towards more complex interactions among robots. No further timeline was disclosed at the time of publication.
Specialized Robots Industrial Automation Biomedical Robotics Robotic Collaboration
AGIBOT Unveils Embodied AI Robotics at IFA 2026 with New Models and Certifications
AGIBOT presented its newest embodied AI robotics innovations at IFA 2026, including the AGIBOT A3 humanoid and AGIBOT X2 Ultra. These robots are designed for various applications, such as retail, industrial operations, and commercial cleaning. The significance of this showcase lies in AGIBOT's commitment to enhancing robotic capabilities in practical environments. The announcement of TÜV Rheinland certifications for its robots further underscores the company's dedication to safety and quality standards in robotics. Looking ahead, AGIBOT's partnership with Tekpoint aims to strengthen its foothold in the European market. No further timeline was disclosed at the time of publication.
AI Robotics Humanoid Robots Commercial Cleaning Retail Technology European Market Expansion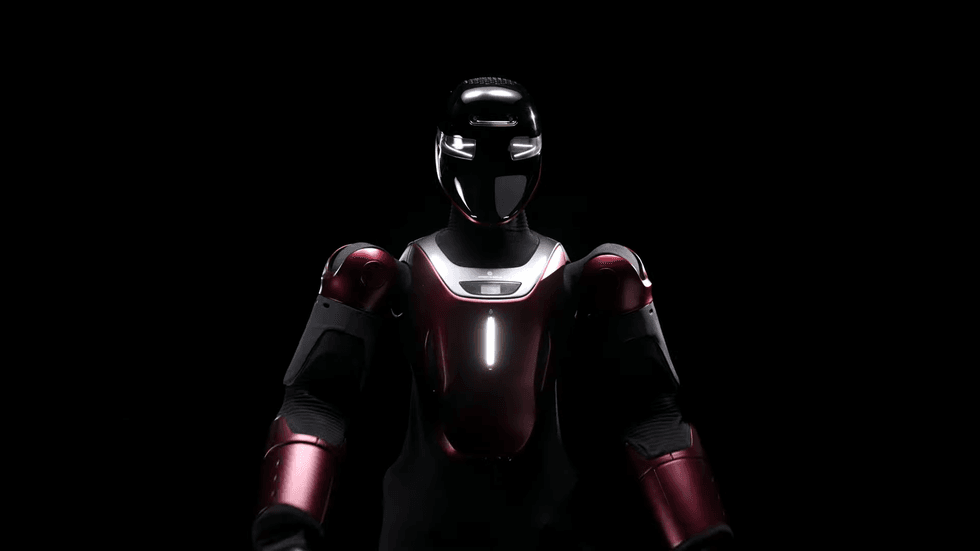
Italian Humanoid GENE.01 Achieves Functional Mobility and Interaction Capabilities
In a remarkable development, the team behind GENE.01 has transformed the humanoid robot into a fully operational platform capable of walking, sensing, and interacting within just six months. This humanoid features a full-body multimodal skin that can perceive touch, proximity, force, and temperature, marking a significant advancement in Physical AI technology. The progress of GENE.01 is crucial as it represents a step closer to safe and natural collaboration between robots and humans. The ability to interact with the environment through various sensory inputs enhances the potential for humanoid robots to be integrated into everyday tasks and settings, thus broadening their application in various industries. Looking ahead, the development of GENE.01 sets the stage for further innovations in humanoid robotics and Physical AI. As the technology evolves, stakeholders will be keen to observe how these advancements can be applied in real-world scenarios and what new capabilities may emerge in the coming years. No further timeline was disclosed at the time of publication.
Humanoid-robots Video-friday Robot-hands Robot-videos Physical-ai Drone-delivery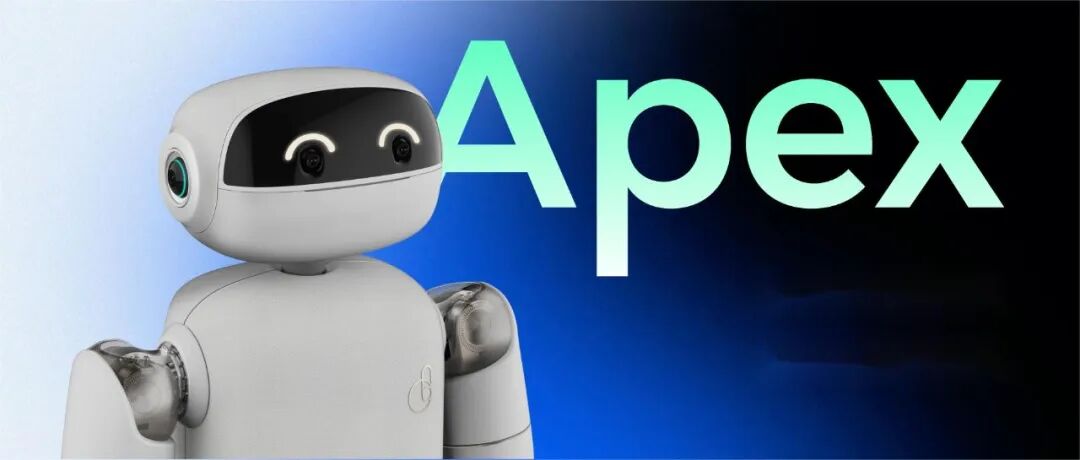
Yuanli Lingji Launches DM0.5 Model and Apex Robot at Action 2026 Conference
On July 9, Yuanli Lingji introduced three key products, including the DM0.5 model and Apex robot, during the Action 2026 Developer Conference. This event highlighted the company's commitment to full-stack capabilities in embodied intelligence, a crucial factor in addressing industry fragmentation and enhancing model architecture with high-quality data. The significance of these product launches lies in their potential to drive commercialization within the embodied intelligence sector. By focusing on full-stack solutions, Yuanli Lingji aims to set itself apart in a competitive market, where the integration of robust data and model frameworks is essential for success. Looking ahead, industry observers will be keen to see how these products perform in the market and whether they can effectively address the challenges of fragmentation. No further timeline was disclosed at the time of publication regarding future developments or additional product releases.
Embodied Intelligence Robotics AI Machine Learning Automation
ByteDance Seedance: How China's Video-Gen Model Turned the Tide
ByteDance has unveiled Seedance 2.0, marking a significant advancement in the realm of video generation technology in China. This innovative model has quickly established itself as the leading force in the market, boasting impressive gross margins ranging from 70% to 90%. The launch, which took place in October 2023, is poised to redefine the artificial intelligence business landscape by setting new standards for profitability and efficiency in video content creation. By leveraging cutting-edge technology and extensive data analysis, ByteDance aims to capitalize on the growing demand for high-quality video content, positioning itself at the forefront of the industry.
News
Small-AI Models Gain Traction Around the World
One morning in 2019, Adebayo Alonge was in a Cape Town hotel room, preparing to demonstrate his startup’s AI answer to a serious problem in African health care: counterfeit medication, which kills thousands of people across the continent every year.The RxScanner is a handheld spectrometer that scans a pill with infrared light, then sends the item’s molecular profile to an AI model equipped with a pharmaceutical database. In seconds, the AI identifies the medication from its molecular profile—or reports that it’s phony.Pharmacies were using the system in more than a dozen countries, including Ghana, Kenya, Myanmar, and Alonge’s native Nigeria. But that morning in South Africa, it didn’t work. “I was shocked,” Alonge says.The spectrometer connected to the AI model—but the data center was 14,000 kilometers away and bandwidth was limited. “Our server was in the United States, and just to get the result of a single scan was taking me over 5 minutes.”So Alonge immediately asked his engineers to shrink the AI model down to a smaller, low-power, unconnected version that could run entirely on his Android phone. They produced it 2 hours later, and that saved the demo.More importantly, the work birthed a new version of his device, which can authenticate a pill in places without broadband, computers, or even reliable electricity. It also turned Alonge into an advocate for this kind of “small AI.”Small AI for Global Health Care AccessSmall AI is a far cry from wealthy nations’ colossal large language models (LLMs), hyperscale data centers, multibillion-dollar investments, and debates about AI consciousness. But for millions of people around the world, the only AI that matters, and often the only kind available, is small. (According to a World Bank Report issued in November, only 0.7 percent of internet users in the world’s poorest countries have used ChatGPT, compared to a quarter of all internet users in the most developed nations.)“Most people are discussing AI from the LLM/generative side. But that needs a lot of computing power, electricity, massive data, and skilled people to manage it,” Ajay Banga, president of the World Bank, said last January at the World Economic Forum, in Davos. “Outside the developed world, other than maybe India and China, very few countries have that combination.”By contrast, small AI can deliver useful, even life-saving services to people in areas that have none of those things, Banga said. In India, where the government’s AI plans call for more development of small AI, many such systems are working for farmers.For example, a drone-based system developed by Bala Murugan and colleagues at the Vellore Institute of Technology, in India, takes photos of cashew plants and quickly identifies those with splotches that indicate disease. All the processing takes place on the drone itself, so there’s no need for a computer on-site, nor for a connection to a central server.Using small language models trained for a specific problem, and sometimes running on cheap, low-power devices, other small-AI implementations have been developed to identify ant infestations in a Uruguayan vineyard, detect the presence of malaria-carrying mosquitoes in a number of nations, and run electrocardiograms from an Arduino device in parts of Brazil that lack access to more complex equipment.“This is the most important area in AI nowadays,” says Marcelo José Rovai, a professor at the Institute of Engineering and Information Systems at the Federal University of Itajubá, in Brazil, who was involved in all three projects. “It’s growing very fast.”Low-Power, Small-AI Models on Devices Small AI models can run on a variety of low-power devices, including [from left to right] an Arduino Nano 33 BLE Sense, a Seeed Wio Terminal, and an Arduino Portenta.Moez AltayebFor Alonge, Rovai, and other advocates, small AI is not just “a promising trend,” as that November World Bank report calls it. It may be, in the long term, the form of AI that will touch the most lives and remain sustainable after some of the giant models become too costly for most users.“I think the future of AI is not like one giant model, at a center. I think it’s millions of small, precise models deployed at the edge, each one solving like a specific problem, a specific context,” Alonge says. This is partly because much of humanity—including people in parts of rich countries as well as the developing world—lives without access to cutting-edge frontier models. But, he says, it’s also because those models are not sustainable.“If someone is not subsidizing it, most people will not be able to afford those models. So those of us who are said to be small-AI developers are the ones who will have to build for the majority of the world,” Alonge says.There is no strict definition of “small AI,” but people often use the term for language models with at most a few billion parameters. (Compare that to cutting-edge models, which can include more than a trillion.) That’s small enough to run directly on a phone or a Raspberry Pi. That’s what allows these applications to run on devices without a connection to a data center and use only a few watts of power, often supplied by a battery or a solar panel.Despite their small footprint, these models aren’t fundamentally different technology from that of gigantic AI models, Rovai says. Many instances of small language models were created the same way the phone-based version of Alonge’s pharmaceuticals scanner was—by “pruning” large models, or removing the parameters that weren’t involved in the task. The result is a system that’s less capable generally but still very good at the specific job it was pruned for, Rovai says. A lighter version of RxAll’s RxScanner spectrometer sends its results to an AI model run locally on a phone to check that a drug’s molecular signature is genuine.RxAllOther small models are created by “distillation.” They are trained to mimic a large model, until their performance approaches that of their “teacher,” Rovai says. In other cases, a larger model’s precision is reduced, for example, so that a model run on 32-bit architecture can run on 8-bit designs. In situations where the machine learning application is being used to classify data or predict patterns (like an ant infestation), it’s trained from the beginning on a small device, not derived from a larger model at all. Running all these small, specialized systems is becoming easier, Rovai says, for two reasons.The first reason is that hardware is getting better and more capable while using less power, he says. This means more and more phones can run small AI—especially those equipped with neural processing units, which are specialized chips that handle AI tasks like facial recognition and changing the brightness, shadows, or contrast in a photo.In 2025, slightly more than a third of all smartphones shipped worldwide were capable of running generative AI, and that figure will reach 45 percent by the end of this year, according to the technology research firm Counterpoint. By the end of next year, slightly more than half of all smartphones will be able to run a small AI model.The second reason Rovai cites is the shrinking footprint of language models. Both Google DeepMind’s Gemma 4 (released in April) and Alibaba’s Qwen 3.5 are “fantastic” for small AI, Rovai says. Both models are “open weight,” meaning users can adjust the connections between parameters to suit their needs. This makes it easy, for example, “to take a lot of data from, say, the milk industry and retrain the model specifically on that,” Rovai says.Rovai illustrated these reasons on a Zoom call, using one of his most recent experiments. Holding up a device, he says, “This is the new Arduino UNO Q—a US $50 device with a Qualcomm chipset. I’m running a language model here, which collects data from sensors and analyzes that data to detect tiny pools of water where mosquitoes might be breeding. It takes 3 watts to run it.”Support for Small-AI DevelopmentConvinced that millions of people are already benefiting from these kinds of applications, the World Bank now actively promotes small AI with grants, mentorship programs, financing, technical advice, and models of government policies that are friendly for small-AI development. For example, in Rwanda, the World Bank is backing a government program to help low-income households get devices that can run AI.All that said, no one claims that large language models are going away entirely. To create a generative AI that can run on a phone or other small device requires the architectural insights, data processing, and results of a larger model, Rovai says. “We need the big models to create these smaller models.” And for all that small AI can benefit people without access to big AI, the technology can’t solve the larger problems of development and digital inequality, Alonge says. Implementing small AI won’t allow nations to escape the challenge of creating an ecosystem to support AI: reliable power, a supply chain that works, and an educational system that develops the talents needed to create AI tools.Though his drug-scanning system can run for days on a phone with no connection, “you still want to be able to enable periodic syncing for updates with new signatures for the medications and analytics,” Alonge says. “And even when you are using batteries, reliable power is important. That phone battery is not going to last forever.”In many parts of the world, the future of small AI isn’t assured, he says. “It works, and many places will eventually need to use it. The question is whether or not the political actors are wise enough to invest in infrastructure to support it long term.”
Small-language-models Artificial-intelligence Llms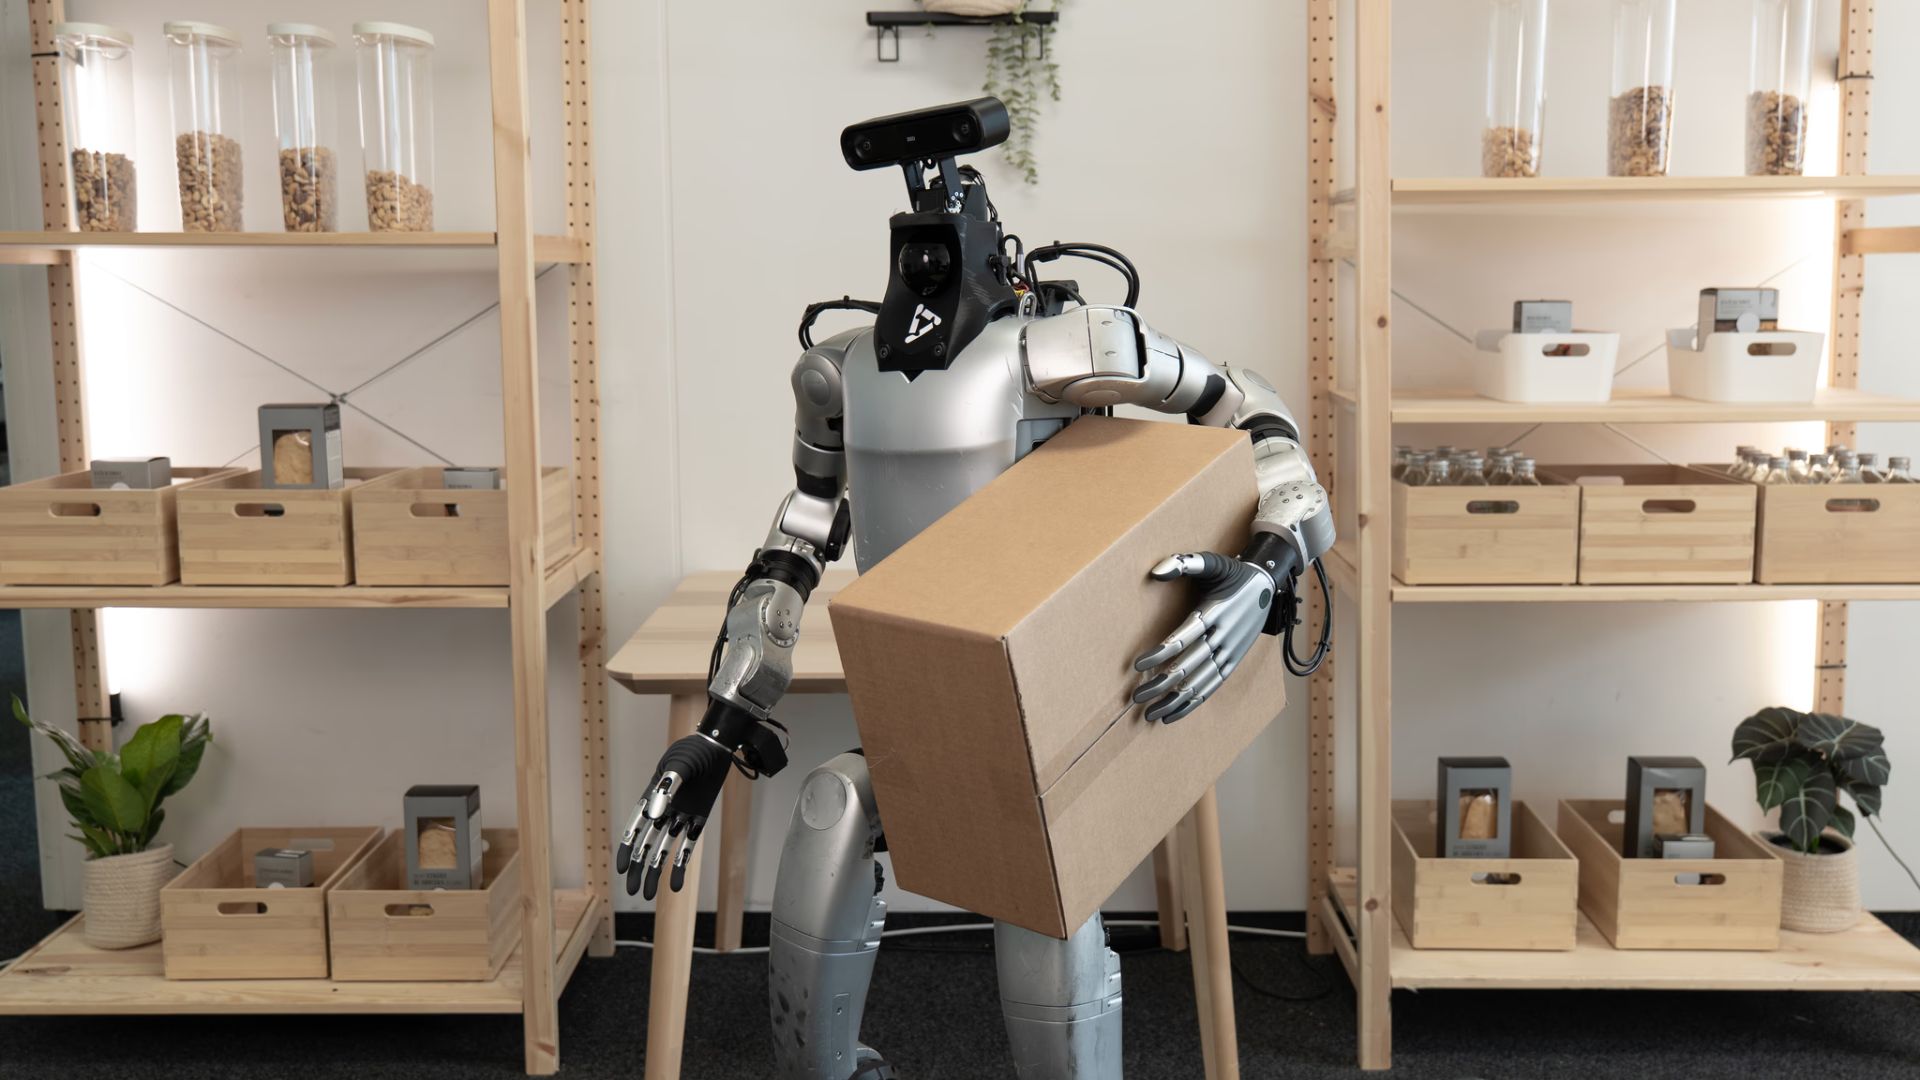
Video: New AI model gives humanoid robots 90 percent success in complex missions
Flexion Robotics has launched Reflect v1.0, an innovative robotics intelligence platform designed to enhance the capabilities of humanoid robots. This groundbreaking technology was unveiled recently, showcasing its potential to revolutionize the interaction between humans and robots. The platform integrates advanced machine learning algorithms, allowing robots to learn from their environments and adapt their behaviors accordingly. The introduction of Reflect v1.0 aims to address the growing demand for more intelligent and responsive robotic systems in various sectors, including healthcare, education, and customer service. By equipping humanoid robots with this sophisticated intelligence, Flexion Robotics seeks to improve efficiency and effectiveness in tasks that require human-like interaction. The development process involved extensive research and collaboration with experts in artificial intelligence and robotics, ensuring that the platform meets the needs of diverse applications. As the robotics industry continues to evolve, Reflect v1.0 positions Flexion Robotics at the forefront of innovation, paving the way for a future where humanoid robots can seamlessly integrate into everyday life.
AI and Robotics
Liquid AI's smallest model yet LFM2.5-230M beats models 4X its size at data extraction, can run 'anywhere'
Liquid AI, a company founded by former MIT computer scientists, has unveiled its latest AI language model, LFM2.5-230M, which is designed for efficient data extraction and local deployment on devices such as smartphones and laptops. Released today, this 230-million-parameter model is noted for its ability to run on various hardware platforms, outperforming larger models like Alibaba's Qwen3.5 and Google's Gemma 3 in specific benchmarks. Targeting developers and engineers, LFM2.5-230M operates under a dual-use commercial license, allowing free access for individuals and companies with annual revenues below $10 million, while larger enterprises must secure a paid agreement. The model distinguishes itself by utilizing the LFM2 architecture, enabling high inference speeds with a minimal memory footprint, making it suitable for edge computing. Liquid AI's launch reflects a broader industry shift towards architectural efficiency rather than sheer parameter counts, as major AI firms focus on models with hundreds of billions of parameters. The LFM2.5-230M is specifically tailored for lightweight data extraction tasks, allowing businesses to automate processes without relying on costly cloud services. In practical applications, the model has been successfully deployed in a humanoid robot, demonstrating its capability to process complex commands efficiently. Available immediately on platforms like Hugging Face, LFM2.5-230M aims to revolutionize how enterprises manage data extraction, moving away from traditional, rigid systems to more adaptable AI-driven solutions.
Technology
ByteDance's Doubao 2.1 Pro Crosses Production Threshold, Seedance 2.5 Video Model Coming July
ByteDance has announced that its Doubao 2.1 Pro has successfully crossed the production threshold, marking a significant milestone for the company. This achievement comes as the tech giant prepares to launch its Seedance 2.5 video model, which is set to debut in July. The advancements in these models reflect ByteDance's commitment to enhancing its product offerings in the competitive tech landscape. The Doubao 2.1 Pro's production success is expected to bolster the company's position in the market, while the upcoming Seedance 2.5 aims to attract a broader audience with its innovative features. As ByteDance continues to innovate, the release of these models underscores its strategy to remain at the forefront of technology and content creation.
AI
Alibaba unveils HappyHorse 1.1 video generation model, launches global AI filmmaking competition
On Monday, Alibaba unveiled HappyHorse 1.1, the latest iteration of its video generation model, marking a significant upgrade from its predecessor, HappyHorse 1.0. This new version boasts enhancements in motion dynamics, subject consistency, prompt adherence, visual quality, and audio generation capabilities. In conjunction with this release, Alibaba announced the HorsePower AI Video Competition, collaborating with Huajing Entertainment Group to encourage innovation in video content creation. The competition aims to engage developers and creators in exploring the potential of the upgraded model, fostering creativity and technological advancement in the field of AI-generated video.
News Feed
Video: Chinese firm shows humanoid and robot arm control by single model in new demo
A Chinese robotics startup has showcased its innovative humanoid robots collaborating with fixed dual-arm robotic systems in a recent demonstration. This event took place in October 2023, highlighting the company's advancements in robotics technology. The demonstration aimed to illustrate the potential applications of these robots in various industries, emphasizing their ability to work in tandem to enhance efficiency and productivity. By integrating humanoid capabilities with dual-arm systems, the startup seeks to address growing demands for automation in sectors such as manufacturing and logistics. The successful collaboration between these robotic systems marks a significant step forward in the field of robotics, showcasing how such technologies can be utilized to streamline operations and reduce labor costs.
AI and Robotics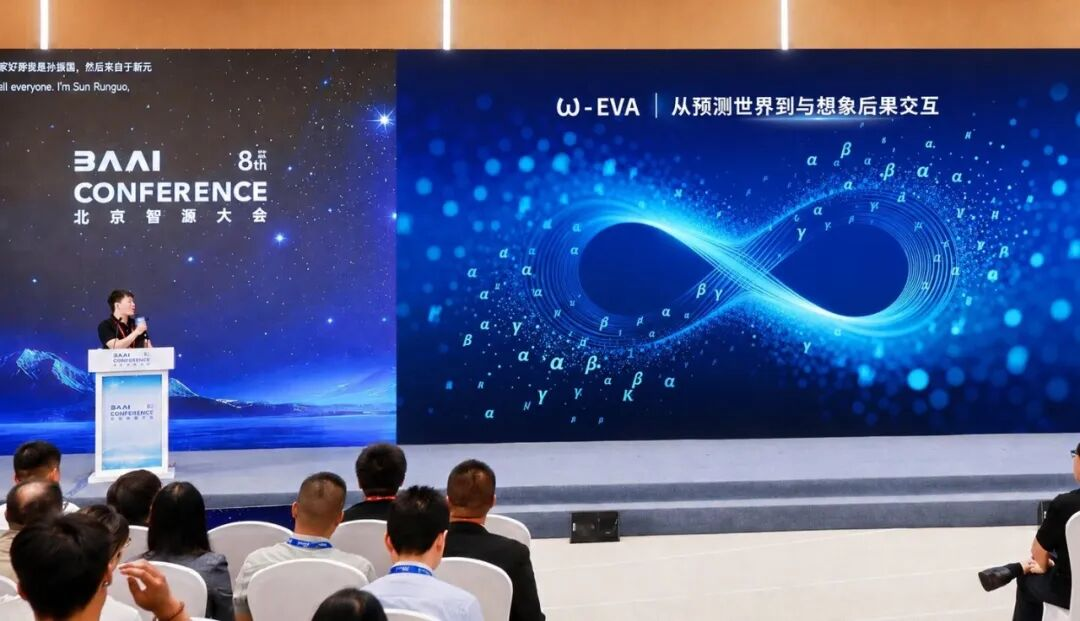
Imagining Consequences Before Robot Actions: The Next Intersection of Xingyuan's ω-EVA and Embodied World Models
At the 8th Beijing Zhiyuan Conference, Xingyuan unveiled its innovative ω-EVA model, marking a significant advancement in the field of embodied intelligence. This model represents a shift from traditional world models, which have typically acted as passive observers, to a more dynamic role in robotic decision-making. By integrating real-time feedback into action generation, the ω-EVA model emphasizes the necessity of predicting outcomes prior to executing movements. This development highlights a broader industry trend towards the practical application of artificial intelligence capabilities, showcasing how robotics can evolve to become more responsive and effective in various tasks.
Embodied Intelligence Robotic Decision-Making AI Models Real-Time Feedback Technology Innovation
ZhiYuan Releases First Open-Source Dataset for World Models Focused on Rich Interaction
On June 3, 2026, ZhiYuan unveiled the second phase of the AGIBOT WORLD 2026 dataset, which centers on the theme of 'Rich Interaction.' This innovative open-source dataset is pioneering in its focus on physical interactions, meticulously documenting both successful and unsuccessful scenarios between robots and their environments. By offering a comprehensive range of data, the initiative seeks to improve world model training, thereby advancing the capabilities of robotic understanding and physical intelligence. This development marks a significant step forward in the field of robotics, as it aims to better equip machines to navigate complex real-world situations.
World Models Robotic Interaction Physical Intelligence Open-Source Datasets
Why Financial Institutions Are Converging on Transaction Foundation Models to Build Their Own Intelligence
Financial institutions have invested significant time and resources in developing artificial intelligence applications, including fraud detection models, credit assessment tools, recommendation systems, and risk management frameworks. However, despite the effectiveness of these specialized models, the industry faces challenges due to the prevalence of siloed systems. These isolated systems hinder the ability to share data and insights across different departments, limiting the overall potential of AI in enhancing operational efficiency and decision-making. As the financial sector seeks to leverage AI more effectively, there is a growing need to integrate these disparate systems to foster collaboration and innovation. This shift is crucial for maximizing the benefits of AI technologies and addressing the evolving demands of the market.
Perceptron Mk1 shocks with highly performant video analysis AI model 80-90% cheaper than Anthropic, OpenAI & Google
Perceptron Inc., a Bellevue-based startup founded by former Meta researchers Armen Aghajanyan and Akshat Shrivastava, has launched its flagship video analysis model, Mk1, aimed at revolutionizing how enterprises utilize AI in real-time video processing. Announced today, this innovative model is priced significantly lower than competitors, at $0.15 per million input tokens and $1.50 per million output tokens, making it accessible for large-scale industrial applications. The Mk1 model, developed over 16 months, excels in understanding complex physical interactions and temporal reasoning, outperforming established models like OpenAI's GPT-5 and Google's Gemini 3.1 Pro in various benchmarks. Its unique architecture allows it to process video streams continuously, maintaining object identity and providing precise analysis of dynamic scenes, which is particularly beneficial for sectors such as security, robotics, and marketing. Perceptron aims to position Mk1 as a leader in the "Efficiency Frontier," balancing high performance with cost-effectiveness. The model's capabilities extend to auto-clipping highlights from live sports and enhancing quality control in manufacturing. A public demo site is available for potential users to explore its functionalities. This launch signifies a significant step towards integrating advanced AI into real-world applications, as the company seeks to make "physical AI" as prevalent as its digital counterpart.
Technology
Shengshu Technology Launches Motubrain World-Action Model
Shengshu Technology has achieved a significant milestone with its Motubrain model, which has secured the top position on both the WorldArena and RoboTwin 2.0 benchmarks. This accomplishment highlights the model's innovative unified world-action approach, allowing humanoid robots to effectively execute long-horizon tasks across various embodiments. The recognition from these prestigious benchmarks underscores the advancements in robotics technology and the potential for enhanced performance in diverse applications.
News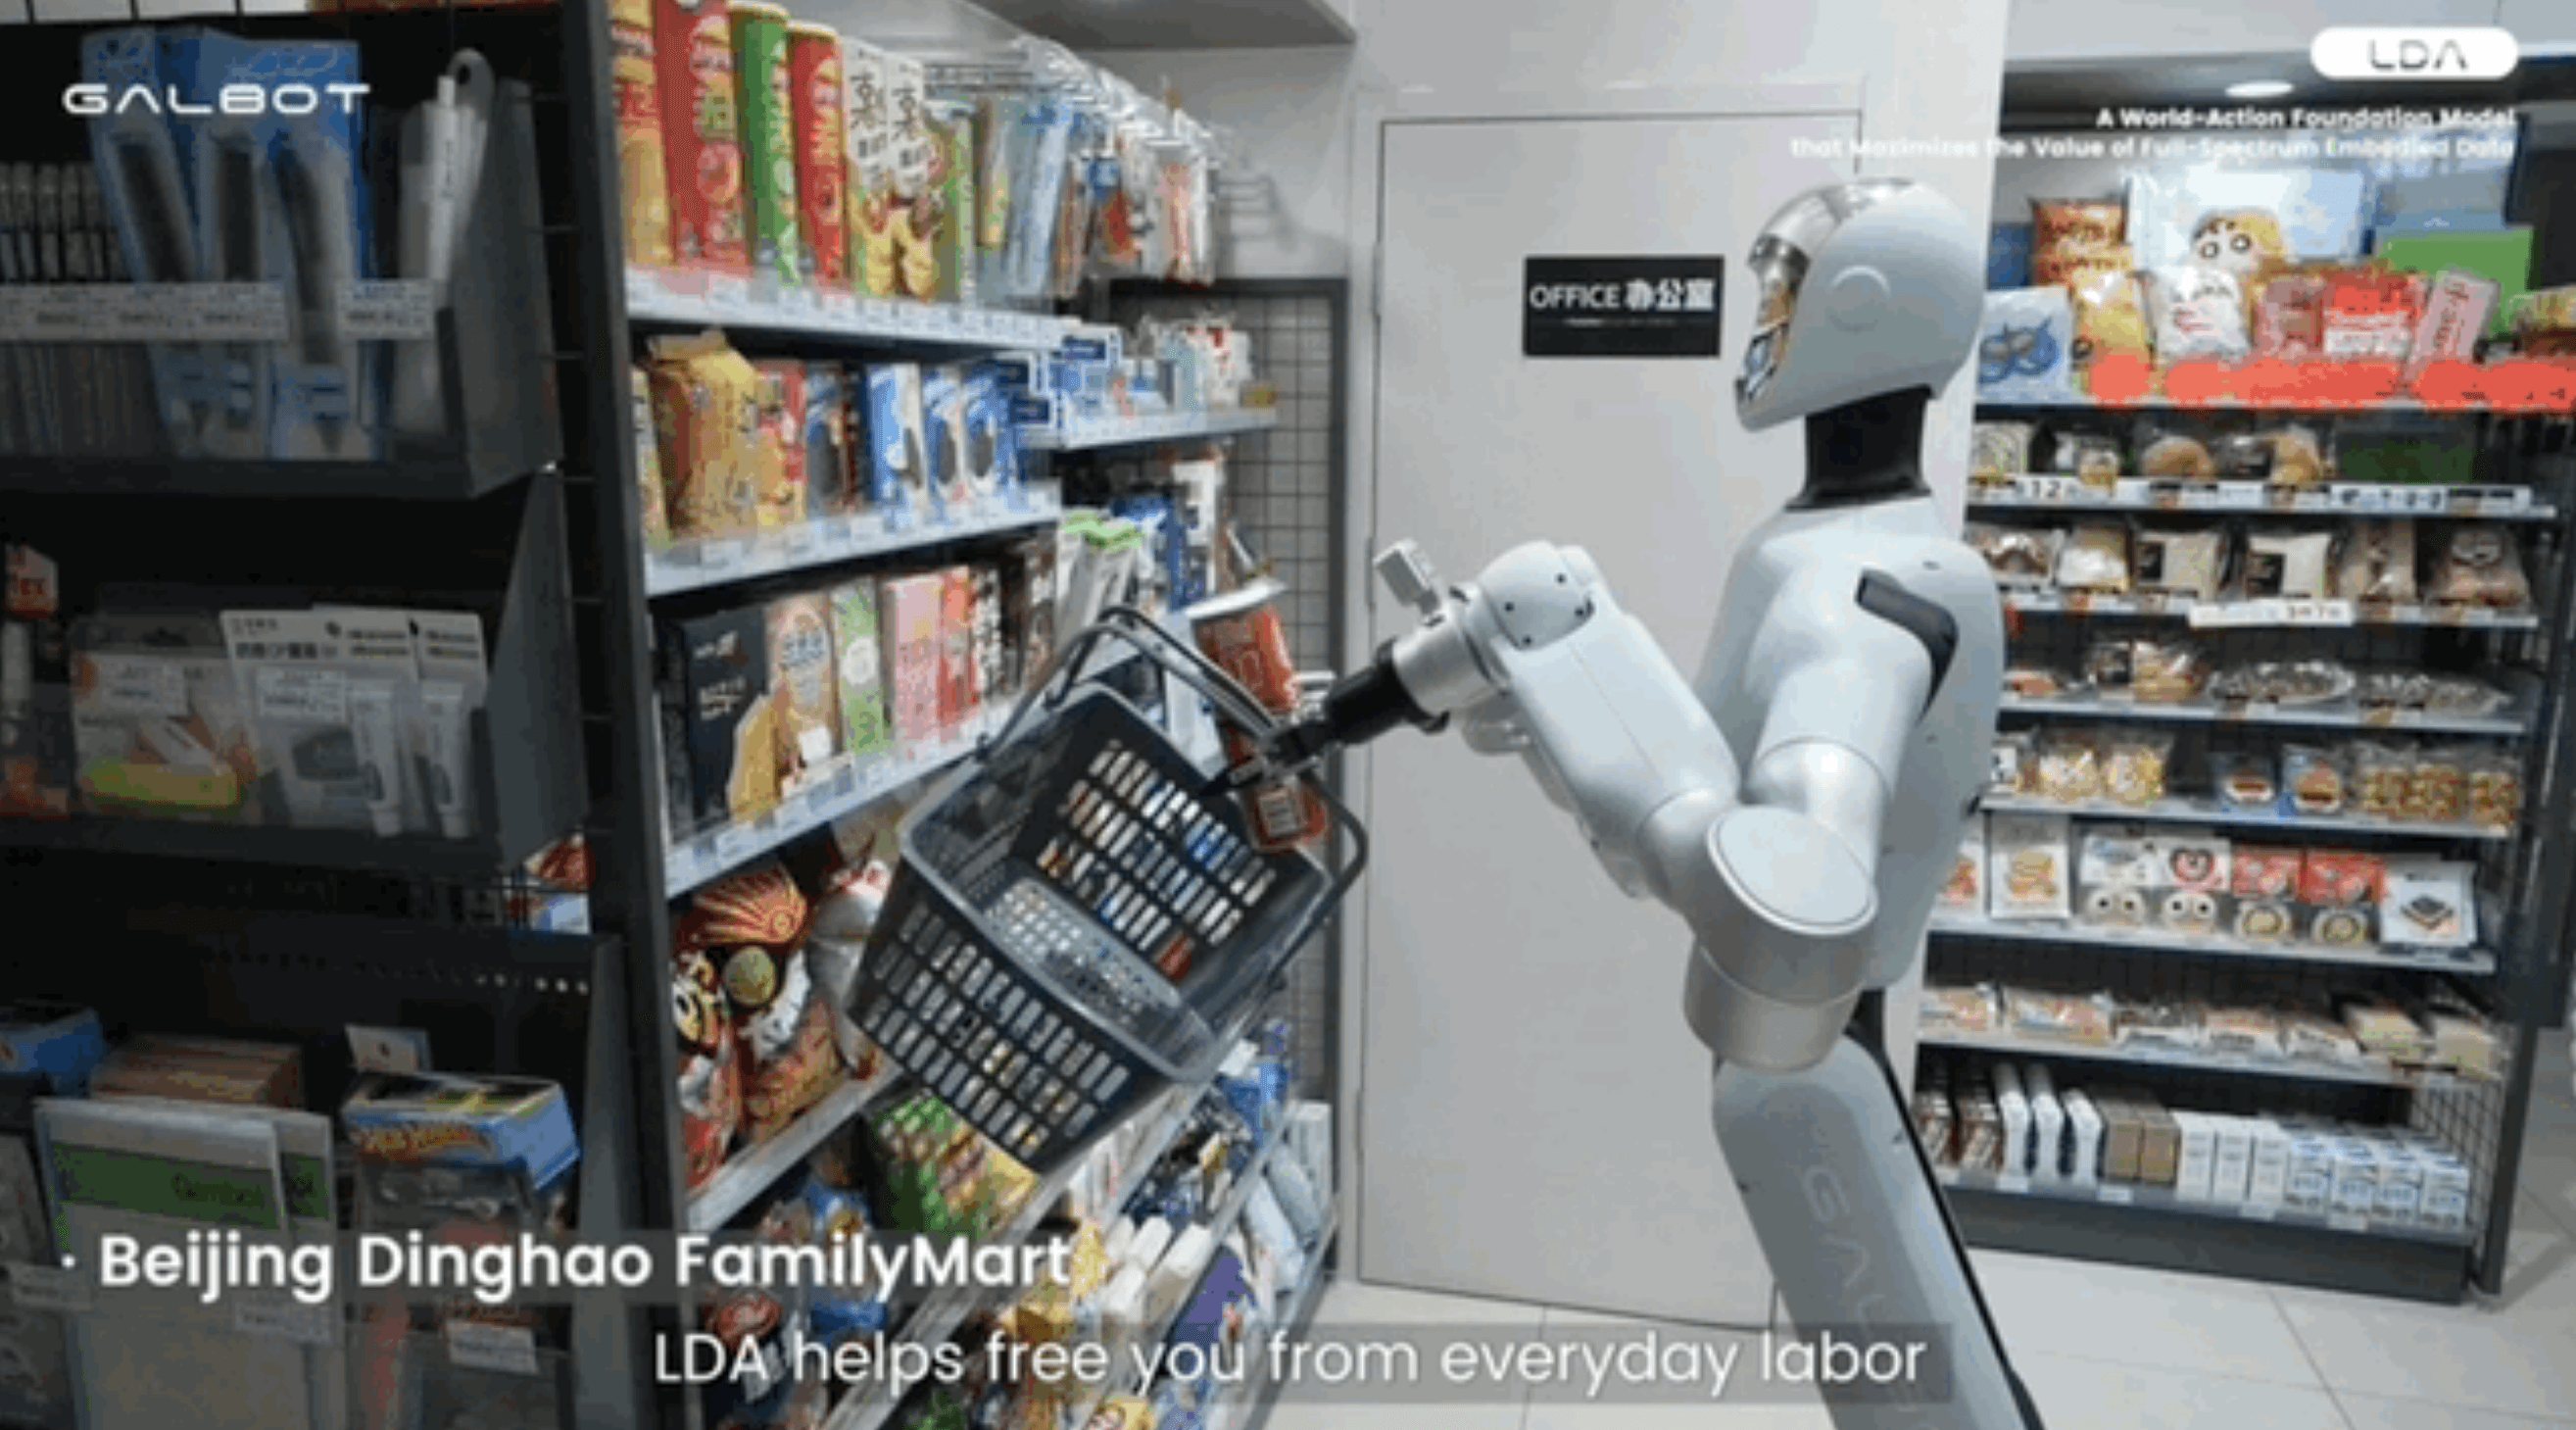
Galbot Launches LDA-1B World-Action Model, Open-Sources Framework
Galbot, China's leading unlisted embodied AI company valued at over RMB 20 billion (approximately $2.8 billion), has unveiled its latest innovation, the LDA-1B. This advanced model, featuring 1.6 billion parameters, integrates world and action learning, showcasing its ability to scale effectively with diverse data sets. The LDA-1B has been open-sourced and is set to be presented at the upcoming Robotics: Science and Systems (RSS) conference in 2026. This release marks a significant step in the field of AI, reflecting Galbot's commitment to advancing technology and contributing to the global AI community.
News
The Era of Eka: New Startup Unveils Vision-Force-Action Model to Crack Dexterity
A team of former researchers from MIT and DeepMind has established Eka Robotics, unveiling a groundbreaking "Vision-Force-Action" (VFA) foundation model. This innovative technology harnesses the power of simulation and tactile sensing to enable robots to perform tasks with superhuman speed and remarkable physical intelligence. The launch marks a significant advancement in robotics, aiming to enhance the capabilities of machines in various applications. By integrating advanced sensory data with real-time decision-making, Eka Robotics seeks to revolutionize how robots interact with their environments. The initiative reflects a growing trend in the tech industry to develop more sophisticated and responsive robotic systems, addressing the increasing demand for automation across multiple sectors.
US Eka Robotics
ShengShu Technology Unveils Motubrain: A Unified "World Action Model" to Solve the Robotics Scaling Problem
ShengShu Technology has unveiled Motubrain, an innovative robotic brain designed to integrate perception and action seamlessly. This new technology aims to surpass traditional Variable-Length Architecture (VLA) models in performance on global benchmarks. The announcement was made recently, showcasing ShengShu's commitment to advancing robotics and artificial intelligence. By creating a hardware-agnostic solution, Motubrain allows for greater flexibility and efficiency in robotic applications, potentially transforming various industries that rely on automation and intelligent systems. The development of Motubrain reflects the growing demand for more sophisticated robotic technologies that can adapt to diverse environments and tasks.
WAM China ShengShu Technology world-model MotuBrain
ShengShu Technology Unveils World Action Model "Motubrain": One Brain, Infinite Possibilities for Robotic Intelligence
Motubrain has emerged as a leader in the field of embodied artificial intelligence, achieving top rankings in two global benchmarks that assess its capabilities in understanding and generating information about the world. This significant milestone was reached in October 2023, highlighting the company's innovative approach to AI technology. By redefining the standards of embodied AI, Motubrain aims to enhance the interaction between humans and machines, making AI systems more intuitive and responsive. The advancements made by Motubrain are expected to have a profound impact on various industries, paving the way for more sophisticated applications of AI in everyday life.
Why Are Large Language Models So Terrible at Video Games?
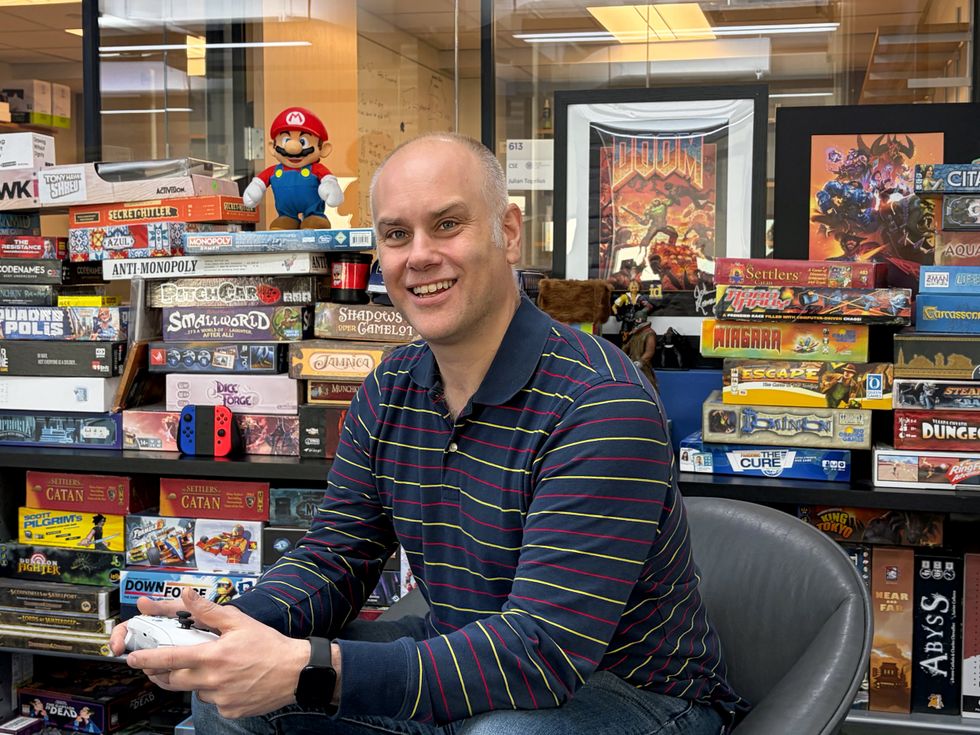
Recent advancements in large language models (LLMs) have led to significant improvements in various domains, particularly in coding. However, a notable limitation remains: LLMs struggle to play video games effectively. Despite some successes, such as Gemini 2.5 Pro defeating Pokémon Blue in May 2025, these models often perform poorly compared to human players, making frequent mistakes and requiring specialized software to assist them. Julian Togelius, director of New York University’s Game Innovation Lab and co-founder of AI game-testing firm Modl.ai, discussed these challenges in a recent interview with IEEE Spectrum. He highlighted that while coding resembles a well-structured game with clear tasks and immediate feedback, video games present a more complex landscape that LLMs have yet to navigate successfully. Unlike games like chess or Go, which have been mastered by AI through retraining, video games vary significantly in mechanics and input requirements, complicating the development of a general game AI. Togelius pointed out that the lack of comprehensive benchmarks for video games further hinders LLMs' performance. While benchmarks have driven improvements in coding, the diverse nature of video games makes it difficult to establish similar metrics. He noted that current LLMs perform poorly even compared to basic algorithms in gaming contexts, primarily due to insufficient training data and challenges in spatial reasoning. Despite their coding capabilities, LLMs cannot engage in the iterative process of game development, which involves testing and refining gameplay. This disparity raises questions about the future of AI in mastering video games and its implications for broader AI applications.
Llms Artificial-intelligence Video-games
1X Unveils 1XWM: The Video-to-Action "Brain" That Lets NEO Imagine Its Chores
1X Technologies has successfully evolved its World Model from a mere simulation tool into an advanced generative "cognitive core." This innovative development enables the NEO humanoid to undertake a variety of new tasks, such as steaming shirts and operating toilet seats, by first visualizing these actions. This transition marks a significant advancement in robotics, showcasing the potential for humanoid robots to perform complex and practical tasks in everyday settings. The enhancement of the World Model is expected to broaden the capabilities of NEO, making it a more versatile assistant in both domestic and commercial environments.
1X-technologies embodied-ai NEO Bernt Børnich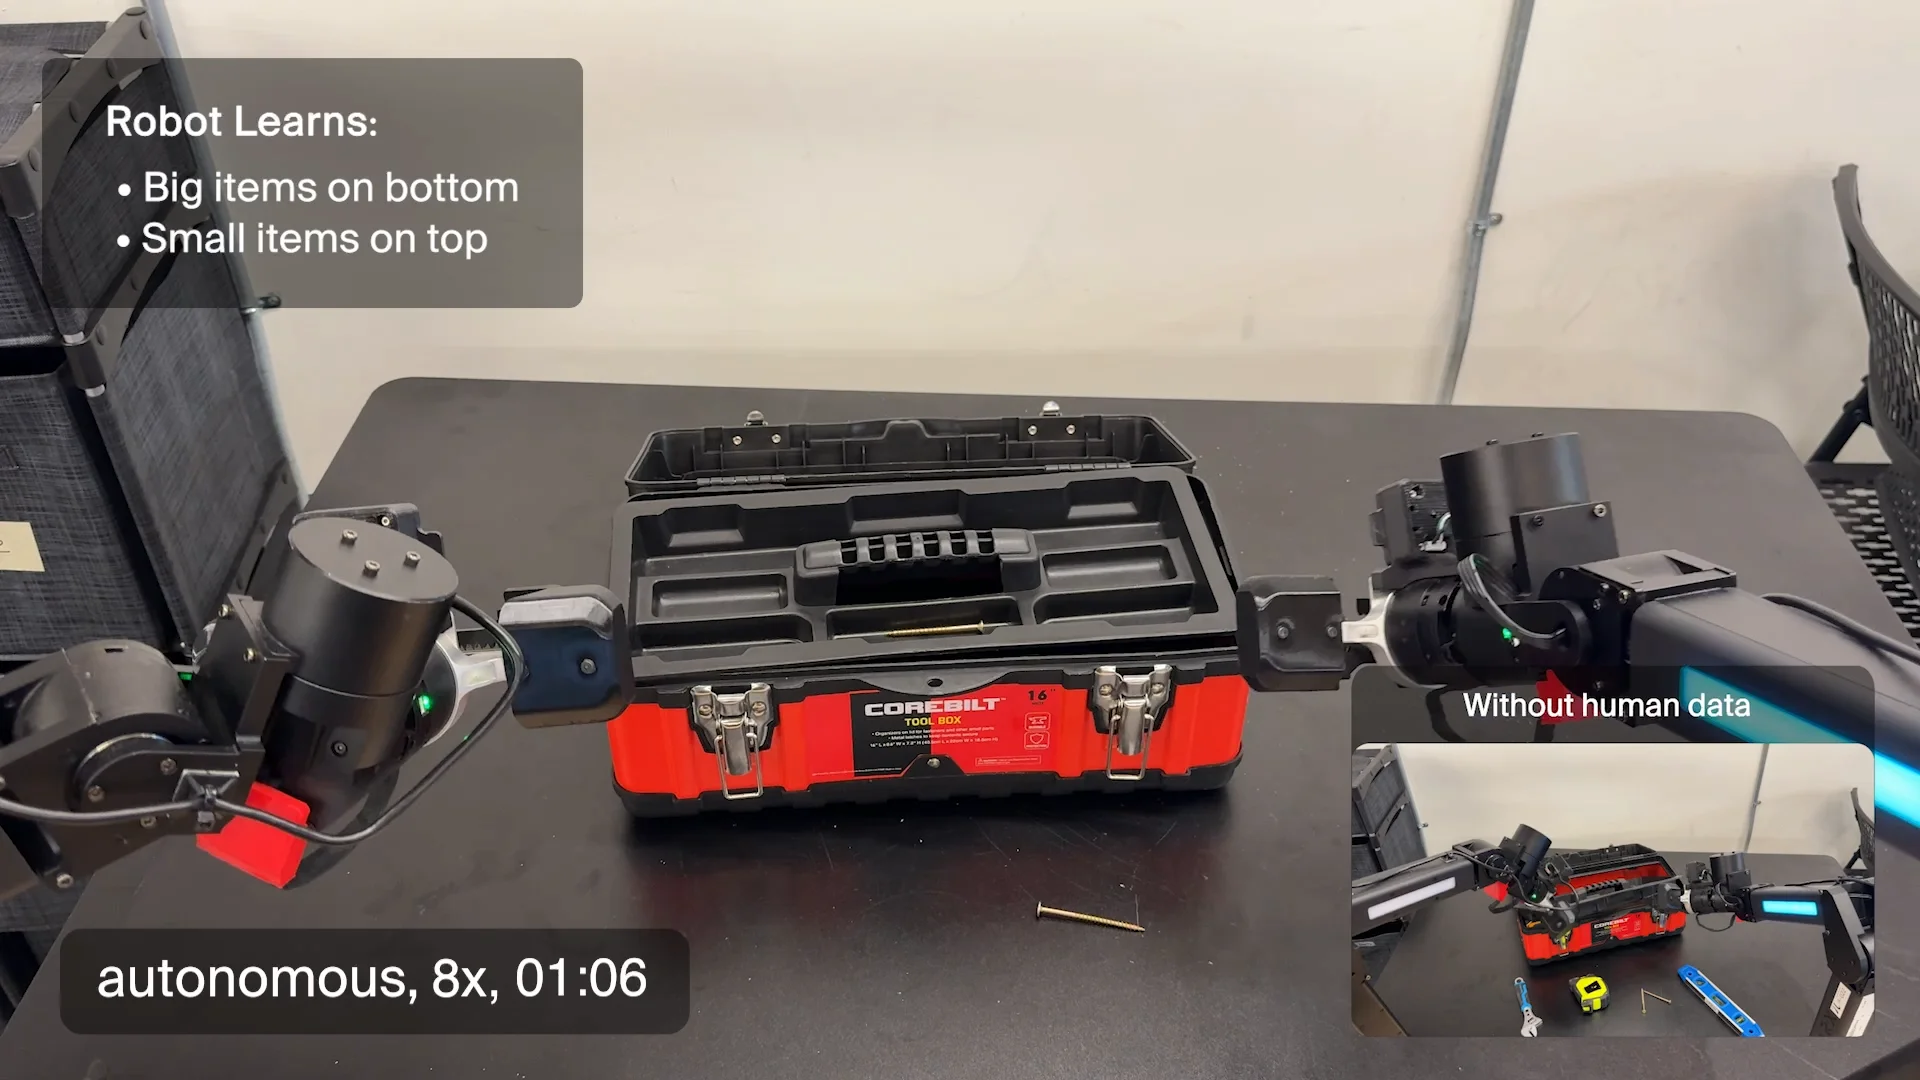
Physical Intelligence Finds 'Emergent' Bridge Between Human Video and Robot Action
A $5.6 billion startup has announced a breakthrough in artificial intelligence, revealing that sufficiently large robot models can autonomously learn to comprehend human video. This development has the potential to address a significant data bottleneck that has long plagued the industry. The startup's findings, which were shared recently, highlight the capabilities of advanced machine learning techniques in enhancing the understanding of visual content. By leveraging large-scale models, the company aims to improve the efficiency and effectiveness of AI systems in processing and interpreting video data, paving the way for more sophisticated applications in various fields. This innovation could transform how machines interact with visual information, ultimately leading to more intuitive and responsive AI technologies.
Data Collection Physical Intelligence embodied-ai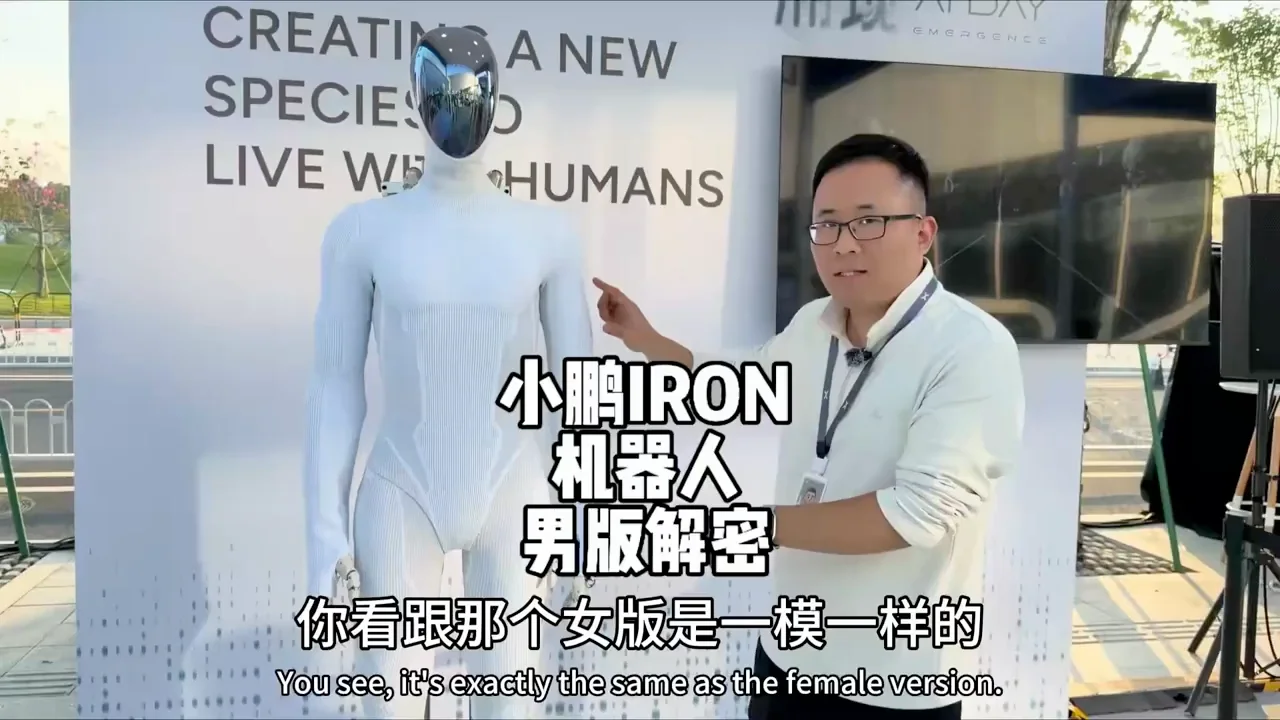
New ''Iron'' Robot Display Model Inspected in Video, Appears to Use Older-Generation Hands
A recent video released by a Chinese journalist offers a detailed examination of Xpeng's humanoid robot, known as "Iron," showcased during the company's AI Day event. The footage highlights the robot's innovative "bionic muscle"-like padding, confirming previously shared design elements. Notably, the video also supports earlier speculation that the models presented at the event do not yet include the advanced "dexterous hands" mentioned in the keynote address. This revelation raises questions about the current capabilities of the robot and its readiness for future applications in artificial intelligence and robotics.
XPeng IRON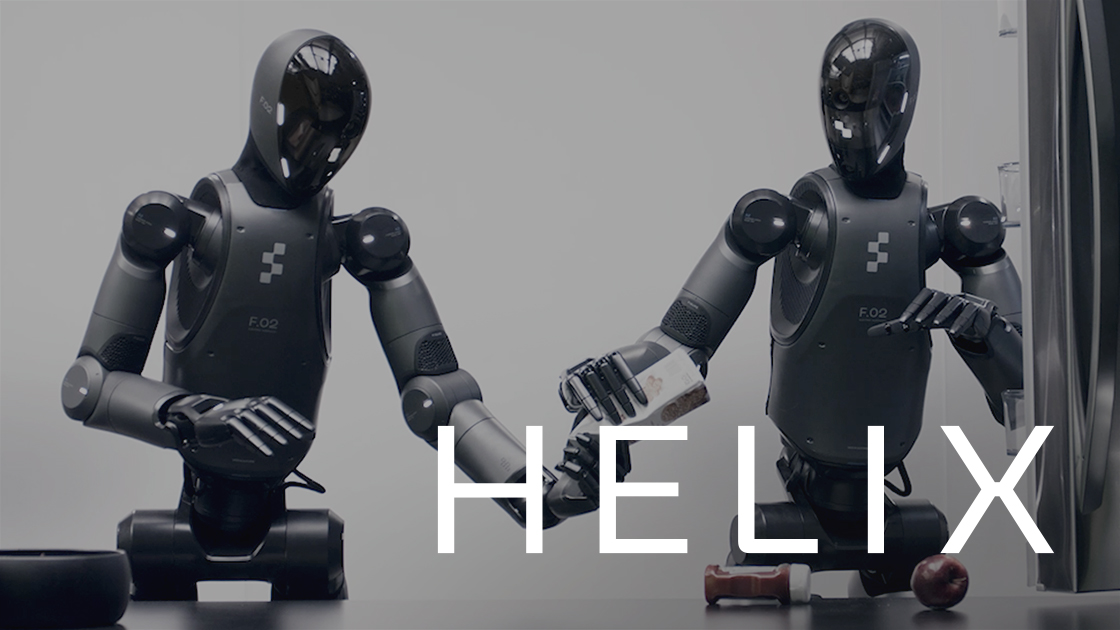
Helix: A Vision-Language-Action Model for Generalist Humanoid Control
Helix, an innovative Vision-Language-Action model, has been developed to enhance humanoid robotics by providing full upper-body control and facilitating collaboration among multiple robots. This cutting-edge technology enables robots to execute tasks involving new objects through natural language prompts, significantly improving their versatility and usability. Notably, Helix operates efficiently on low-power GPUs, positioning it for commercial applications. With its capabilities, Helix is set to revolutionize the field of robotics, making advanced robotic interactions more accessible and practical for various industries.
robotics AI machine learning humanoid robots automationRobotics needs a service framework.
RSF defines a common language for robot service capability, lifecycle operations, certification pathways, and service-provider networks.
Join the RobotToday community on LinkedIn
Daily robotics news, in-depth analysis, conference highlights, and discussions with professionals worldwide.