

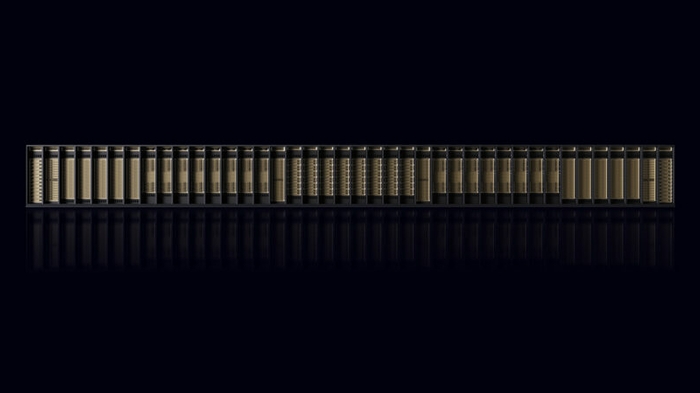
NVIDIA has unveiled the Vera Rubin NVL72, showcasing its impressive performance in the MLPerf Inference v6.1 benchmarks. The NVL72 demonstrates up to 3.7 times higher throughput than the GB300 NVL72 on the Qwen3-VL benchmark and up to 2.5 times higher on DeepSeek-R1, highlighting its efficiency in AI inference tasks.
This advancement is significant for organizations focusing on AI infrastructure, as it emphasizes the importance of performance, scaling efficiency, and software optimization in driving long-term inference economics. The Vera Rubin NVL72's design allows for high utilization across various workloads, enhancing revenue generation while reducing costs per token.
Looking ahead, the introduction of the MLPerf Endpoints benchmark will provide standardized metrics for evaluating agentic inference workloads, further refining performance measurement in AI. The ongoing innovations from NVIDIA, particularly in disaggregated serving and expert parallelism, are expected to continue shaping the future of AI inference performance.
Editor's Note
The launch of the NVIDIA Vera Rubin NVL72 marks a pivotal moment in AI inference technology, emphasizing the need for robust performance and efficient scaling in enterprise applications. As organizations increasingly rely on AI for decision-making, the ability to optimize infrastructure and software will be crucial for maintaining competitive advantage. The advancements in performance metrics and benchmarks will likely influence procurement strategies in the robotics and AI sectors.











Leave a comment