

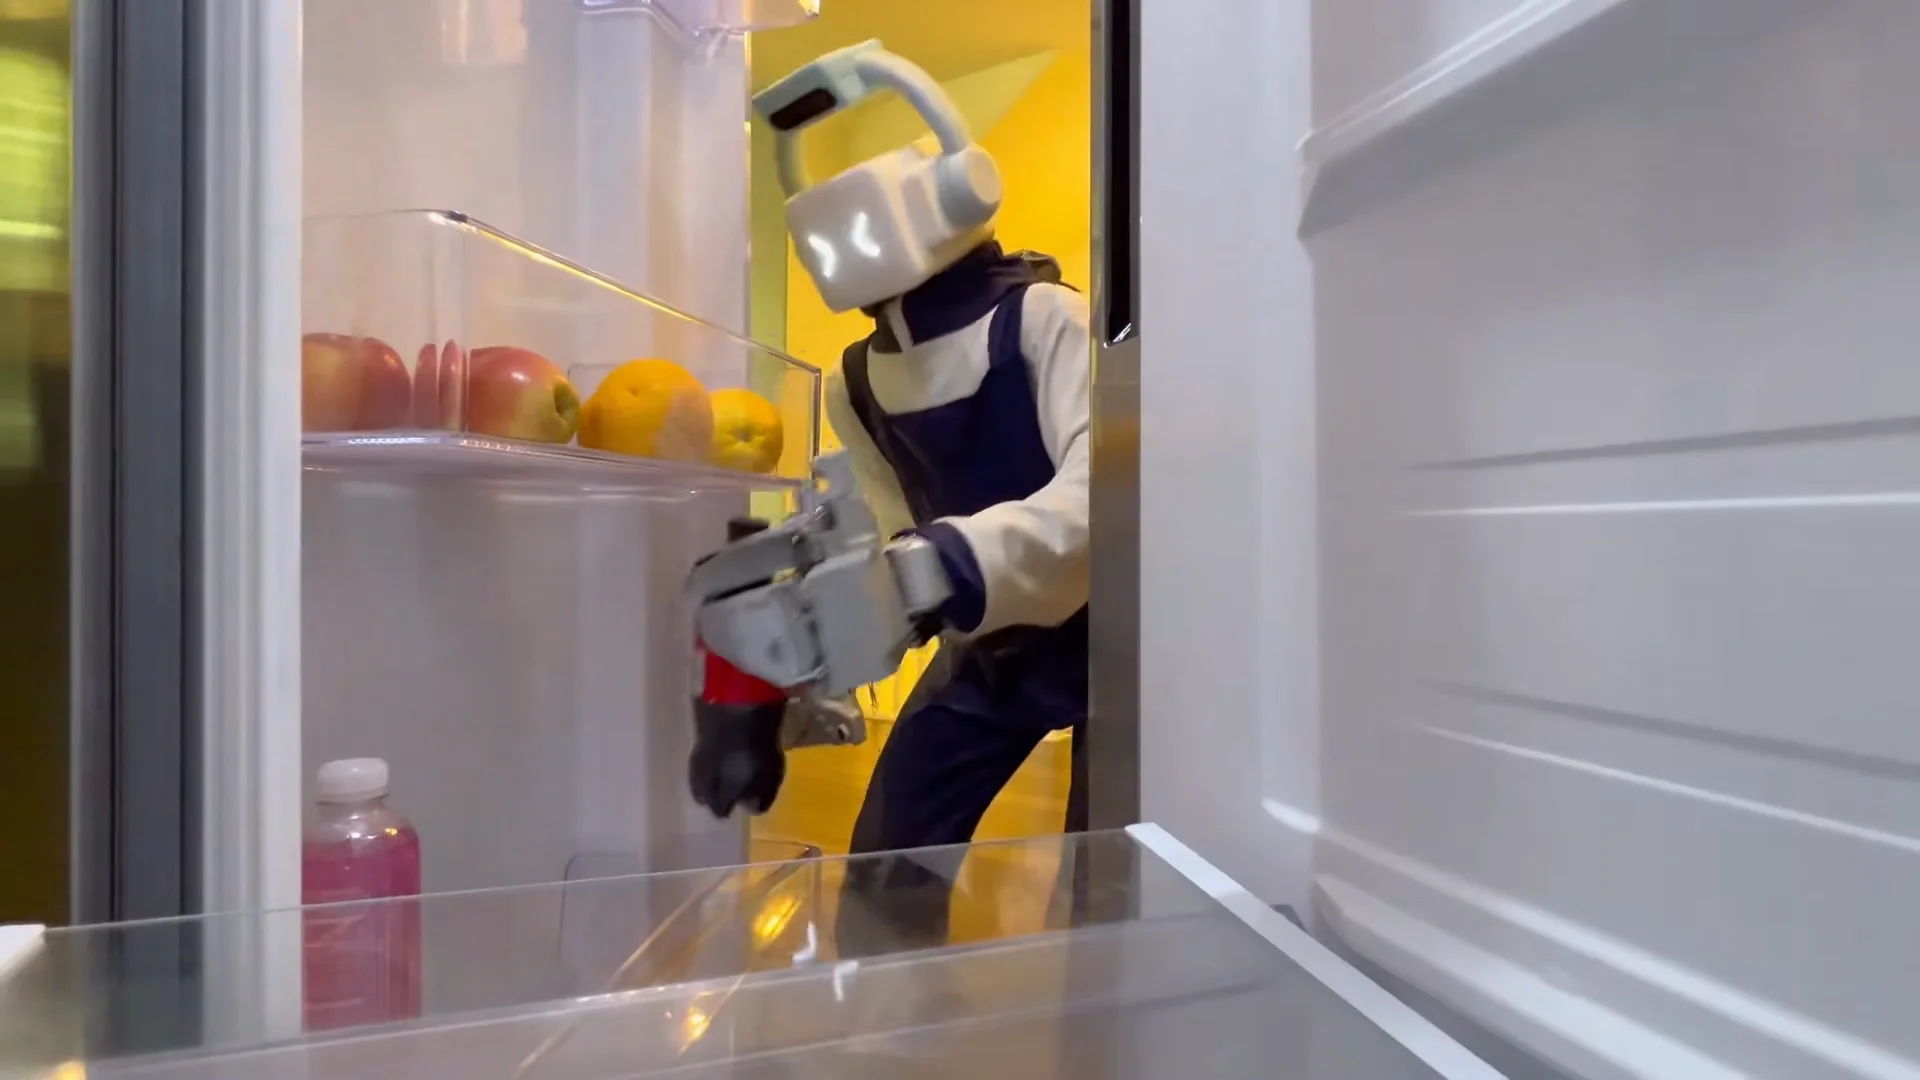
Reward AI has officially launched its foundation model, OM-1, which aims to revolutionize robot manipulation by learning directly from human demonstrations. This approach seeks to eliminate the need for teleoperation and on-robot training, addressing the limitations of traditional methods that can distort training data.
The significance of Reward AI's OM-1 lies in its innovative use of the Omnibody stack, which integrates hardware and multimodal data capture to train robots on natural human movements. By utilizing a specialized wearable glove, the company captures nuanced human dexterity without the constraints of typical robotic systems, allowing for more effective training.
Looking ahead, Reward AI's approach could reshape the landscape of robotic training and manipulation. The company claims that OM-1 can learn complex tasks with minimal human demonstration data, setting a new standard for efficiency in robot learning. No further timeline was disclosed at the time of publication.
Editor's Note
The introduction of Reward AI's OM-1 highlights a pivotal shift in the robotics sector towards more intuitive human-robot interaction. By focusing on direct learning from human actions, the company is addressing critical challenges in data collection and training methodologies. This innovation could significantly impact how robots are integrated into various applications, from domestic tasks to industrial automation.













Leave a comment