

Industry Briefing
A single destination for timely, editor-curated robotics news from around the world.
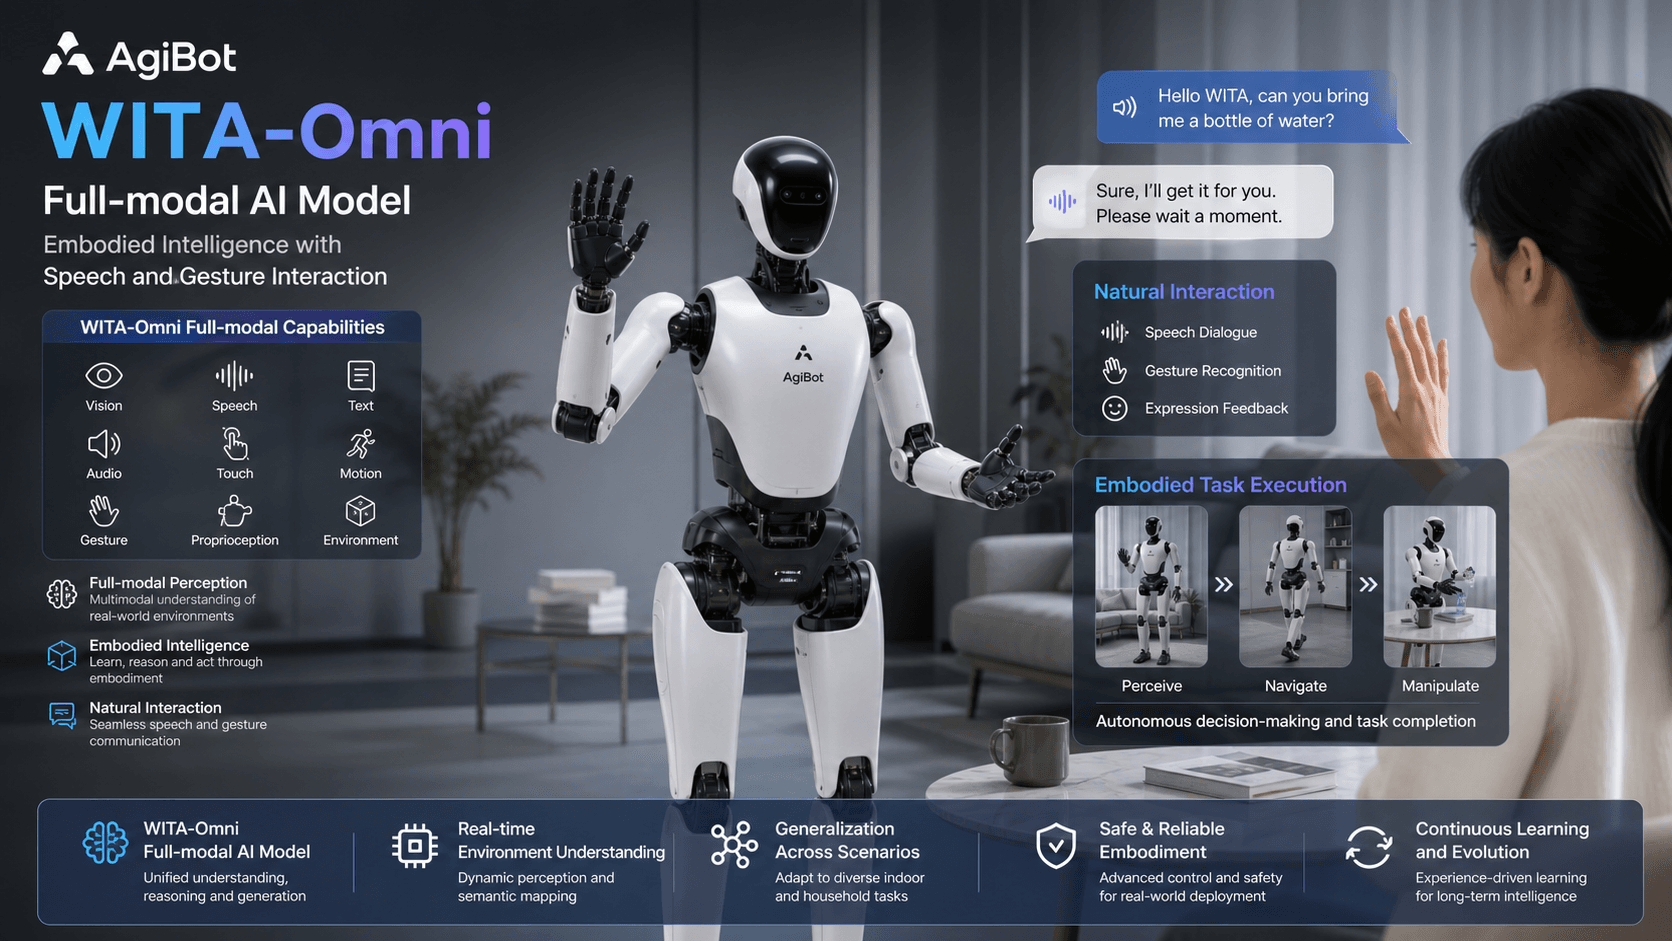
AgiBot WITA-Omni Achieves Top Score on DailyOmni Benchmark, Surpassing Major Competitors
AgiBot WITA-Omni has achieved a score of 85.21 on the DailyOmni benchmark, securing first place in 6 out of 8 indicators. This performance surpasses notable competitors such as Google Gemini, ByteDance Doubao, and Alibaba Qwen in the realm of embodied cross-modal understanding. The significance of this achievement lies in the innovative Thinker-Talker-Actor architecture utilized by AgiBot WITA-Omni. This architecture effectively synchronizes speech, action, and expression on a single timeline, enhancing its capabilities in cross-modal understanding and interaction. Looking ahead, the performance of AgiBot WITA-Omni on the DailyOmni leaderboard may influence future developments in embodied AI technologies. No further timeline was disclosed at the time of publication.
Technology
WITA-Omni Preview Achieves Top Ranking in DailyOmni's Global Multimodal Understanding Assessment
Recently, DailyOmni announced its latest evaluation results, revealing that WITA-Omni Preview, developed by Zhiyuan, topped the rankings with a score of 85.21. This model surpassed leading competitors such as Qianwen, Gemini, Doubao, and NVIDIA, achieving first place in six out of eight sub-indicators. DailyOmni is recognized as an authoritative third-party ranking for assessing audio-video temporal alignment and cross-modal reasoning capabilities. The significance of this achievement lies in WITA-Omni's advanced ability to integrate audio and visual information, which is crucial for humanoid robots interacting in dynamic physical environments. Unlike traditional multimodal models that primarily focus on digital content, WITA-Omni excels in real-time judgment of sound attribution and event sequencing, addressing a key bottleneck in human-robot interaction. Looking ahead, Zhiyuan aims to enhance the WITA-Omni model further, focusing on its application in various commercial and public service scenarios. No further timeline was disclosed at the time of publication.
Multimodal AI Embodied Intelligence Robotics Audio-Visual ProcessingRobotics needs a service framework.
RSF defines a common language for robot service capability, lifecycle operations, certification pathways, and service-provider networks.
Join the RobotToday community on LinkedIn
Daily robotics news, in-depth analysis, conference highlights, and discussions with professionals worldwide.






